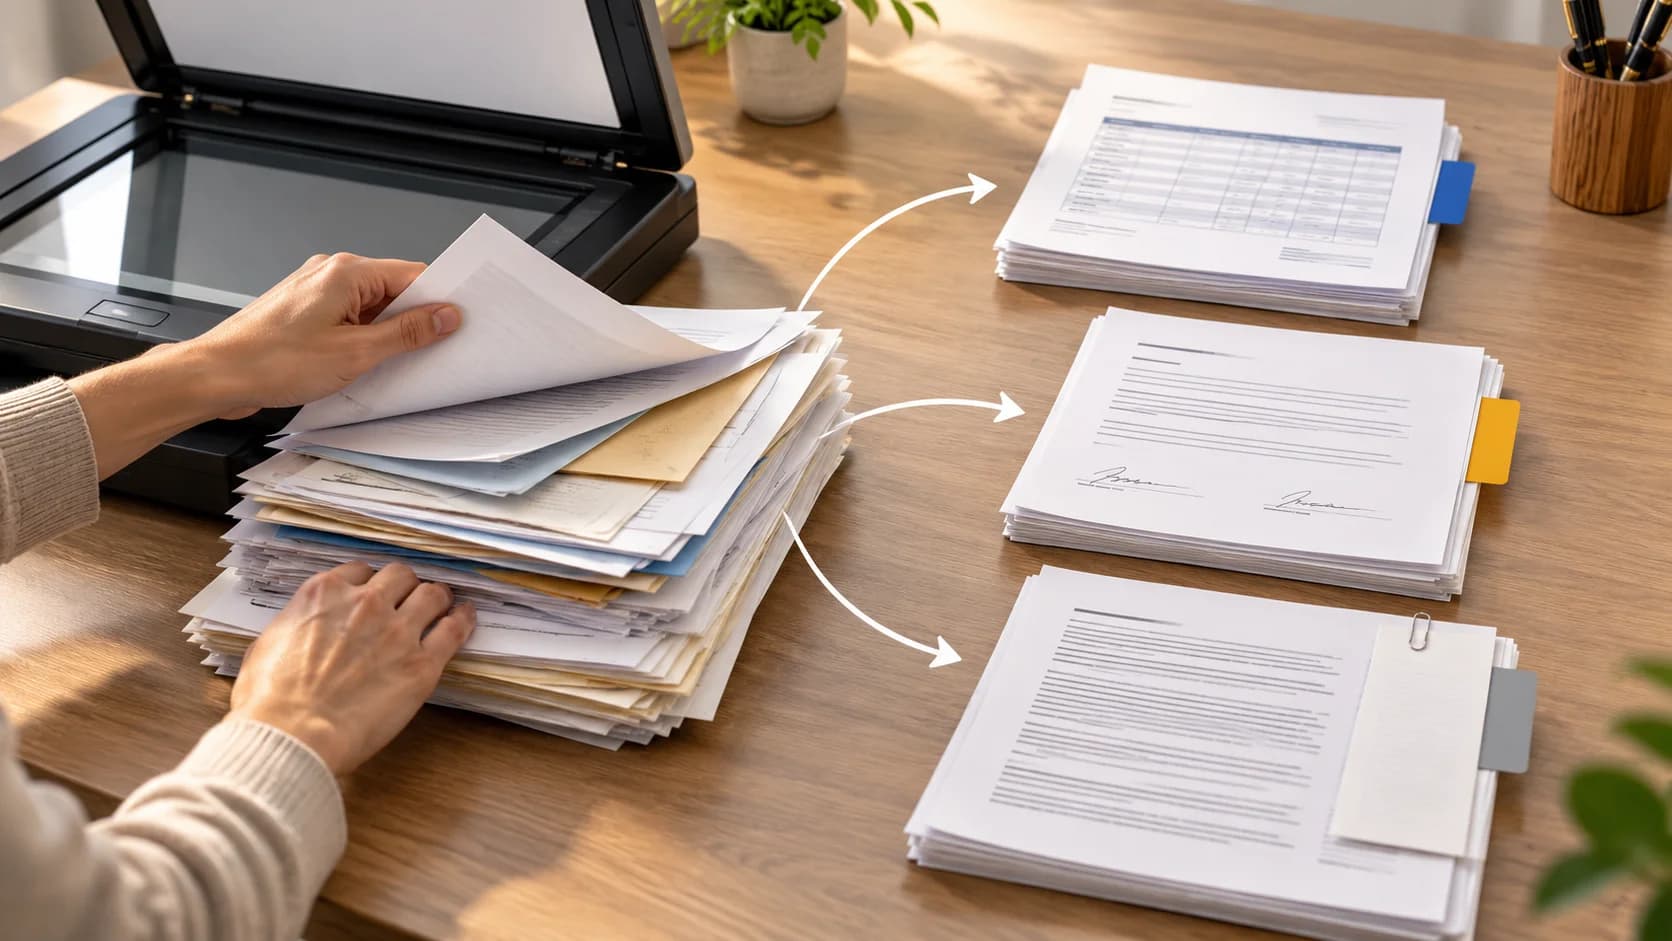
To split a scanned PDF with invoices, service acceptance acts, and contracts, first define the boundaries of each document, confirm any ambiguous transitions, and only then create separate files. OCR can recognize the text, but it does not define those boundaries by itself. Below are answers for a document workflow manager and an integration specialist who need to route parts of an incoming packet to the right handler.
This article focuses on splitting by whole pages using Google Cloud Document AI as an example. It is documented guidance and tutorial examples, not a report on deploying the service on company documents. Cloud availability, billing terms, and whether data transfer is allowed must be checked before uploading files. Information verified on October 31, 2026.
How is AI-based PDF splitting different from regular splitting?
Regular splitting cuts at fixed pages: for example, every two pages. An AI splitter tries to find logical documents based on content. In a packet with an invoice, an act, and a contract, the parts may vary in length, so a fixed interval is inconvenient.
For more on the separate recognition task, see OCR for Business. In Google Document AI terminology, classification determines the type, splitting determines document composition, and extraction retrieves the needed fields. For business use, these are different outcomes: knowing that you have an invoice is not enough to get its amount or a separate PDF.
When do you need AI, and when are rules enough?
Start with rules if the boundaries are already known: separate email attachments, a document-start barcode, or stable formatting. Preserve those cues when handing the file off for processing. A model is useful where packets are assembled unpredictably and simple cues are regularly missing.
| Incoming material | Suggested approach | Output you should get |
|---|---|---|
| One invoice as a separate attachment | Immediate classification or extraction | Fields from the source document |
| A single PDF with reliable separators | Splitting rules | Files by predefined boundaries |
| A scan of invoices, acts, and contracts with no separators | Boundary and type prediction | A verifiable map of parts |
| Two documents on one page | Separate page-region handling | Prepared fragments, then documents |
These are editorial selection criteria, not a product benchmark. Page-based splitting does not solve the final problem: if the act and the invoice occupy different halves of the sheet, a page-number map alone is not enough.
What should you prepare before uploading the packet?
Prepare a copy of the file, a list of expected types, and notes for ambiguous cases. For example: should an appendix to a contract stay with the contract, or become a standalone document? Both rules can make sense, but the model and the human reviewer must follow the same one.
For the first pass, use de-identified material that you are allowed to send to the chosen service. Keep the original separately. Do not replace it with automatically generated parts: otherwise, an error at the boundary will make reprocessing harder.
Custom Splitter supports custom classes; the documentation describes pre-trained options and training on your own documents. Having a pre-trained model does not prove quality on Russian-language acts in your form.
Does Document AI create separate PDFs automatically?
No. The splitter returns information about parts in JSON, and the physical file creation is done separately. Google points to Document AI Toolbox utilities for this. That distinction matters when defining the task for the integrator: “get the boundaries” and “write the files to storage” are different operations. Splitter behavior documentation.
The suggested result of the first stage is a map: the original packet ID, the type of each part, the source pages, and the reviewer’s decision. In the second stage, the application creates files from the confirmed map. In the third, it sends them to the field handlers. Successfully getting JSON does not mean all three stages are complete.
Why can the first page in JSON look like an empty object?
In Entity.pageAnchor.pageRefs[] the page field is zero-based. A zero value may be omitted in serialized JSON: {} in this context means the first page. It is not an empty scanned page. This rule applies specifically to the page-reference object, not to any empty object in the response. Split format description.
A manually prepared tutorial fragment:
{
  "pageRefs": [{}, {"page": "1"}]
}
It corresponds to the first and second pages. At the same time, pages[].pageNumber uses one-based numbering, as explained in the Document AI response guide. Do not apply the same +1 adjustment to all fields: first determine whether it is an index or a displayed number.
What does a reviewer-friendly split map look like?
Show the source page numbers, type, and decision status. Below is a fictional six-page packet; this is an example of presentation, not an actual API response.
| Part | Type | Source PDF pages | Decision |
|---|---|---|---|
| A | Invoice | 1–2 | Confirm after review |
| B | Act | 3 | Confirm after review |
| C | Contract with appendix | 4–6 | Clarify the rule for the appendix |
In the interface, it is useful to open the last page of the current part and the first page of the next one side by side. The reviewer can see whether a signature or table has been cut off from the previous document. To correct the boundary, they need the source packet, not just the extracted text.
Can you use one confidence threshold, such as 0.95?
There is no universal threshold. A model’s high confidence by itself is not a guarantee of a correct boundary. In the Custom Splitter recommendations the threshold is suggested based on historical errors, taking into account the acceptable risk for the business process.
A practical starting choice is human confirmation before file creation. If you later have a labeled history, separately review document types and errors: an incorrect transition between parts, the wrong class, a missing page. The value 0.95 here is an example threshold under discussion, not a vendor recommendation or the result of our test.
Why doesn’t good OCR prevent splitting errors?
Because correct text and correct page assignment are different properties. A model may read the signature correctly but attach the sheet to the next act. Then the next handler will receive someone else’s page.
Work through the cause one step at a time: open the source scan, compare the text and block layout, then compare the boundary map with company rules. Response Processing Guide distinguishes between recognized text and document structure. If the text is wrong, work on input quality and recognition; if the text reads correctly but sections are mixed up, fix the boundaries and class descriptions.
What should you do with blank pages, attachments, and rescans?
Set explicit rules before automatic deletion. A blank page may be a technical separator; an attachment may belong to the contract; a rescanned page may contain a different signature. Simple image similarity does not prove that a page can be discarded.
Suggested process: flag the questionable page, keep it in the source file, show the reviewer the surrounding pages, and record the decision in the map. For example, "page 5 — back side with no content, stays inside the contract" is clearer than a blanket "delete blank pages." These are rules for the proposed workflow; they are not built-in Google behavior.
How can you tell that splitting finished successfully?
Check the result against the source, not just the presence of new files. For the sample package above, there should be parts with pages 1–2, 3, and 4–6 if the employee confirmed that exact map. In each file, the page order should match the original. Open the parts and make sure they are readable.
For a real workflow, define in advance whether gaps and duplicate inclusion of a page are allowed. If not, each page must belong to exactly one part. If exceptions are allowed, there should be a reason for them. Then verify the output type against the next processor: a contract should not be sent to bank statement field extraction. These are suggested result checks; they were not performed on a live workflow here.
What limitations should you check for a specific service version?
Check the processor type, model version, supported input, region, and the limits of the selected processing mode. Conditions from one version cannot be transferred to another. In particular, the documentation Custom Splitter separately warns that the listed 1.6 Release Candidate version does not support data residency. Choosing a project region does not replace checking this condition.
Do not start by uploading the entire archive. First confirm access to the required processor and whether the selected data is allowed to be processed. General platform limits are collected on the Document AI limitspage. Cost, payment availability, and Russian-language quality were not measured in this FAQ; the article does not promise that a foreign cloud will be suitable for a specific Russian company.
How Vladimir Lomtsev’s AI Studio helps with document workflows
Vladimir Lomtsev’s AI Studio can help connect batch splitting with downstream document processing:
- define the types of incoming documents and the rules for assigning attachments;
- prepare data for computer vision and field extraction;
- design the transfer of confirmed parts into enterprise systems while preserving the link to the original.
The first step is to choose one incoming workflow and prepare an anonymized package that is allowed to be analyzed, along with the expected document set. From there, you can discuss the scope of the task and the appropriate processing deployment. Discuss the task.
What to do with the first package
Create a "type — source pages — decision" map, confirm disputed boundaries, and generate files only according to the agreed map. Preserve the link between each part and the original. If the structure is predictable, start with rules; if the boundaries depend on content, consider an AI splitter with human review. The main result is separate, readable documents with the correct contents, ready for extraction of the required fields.