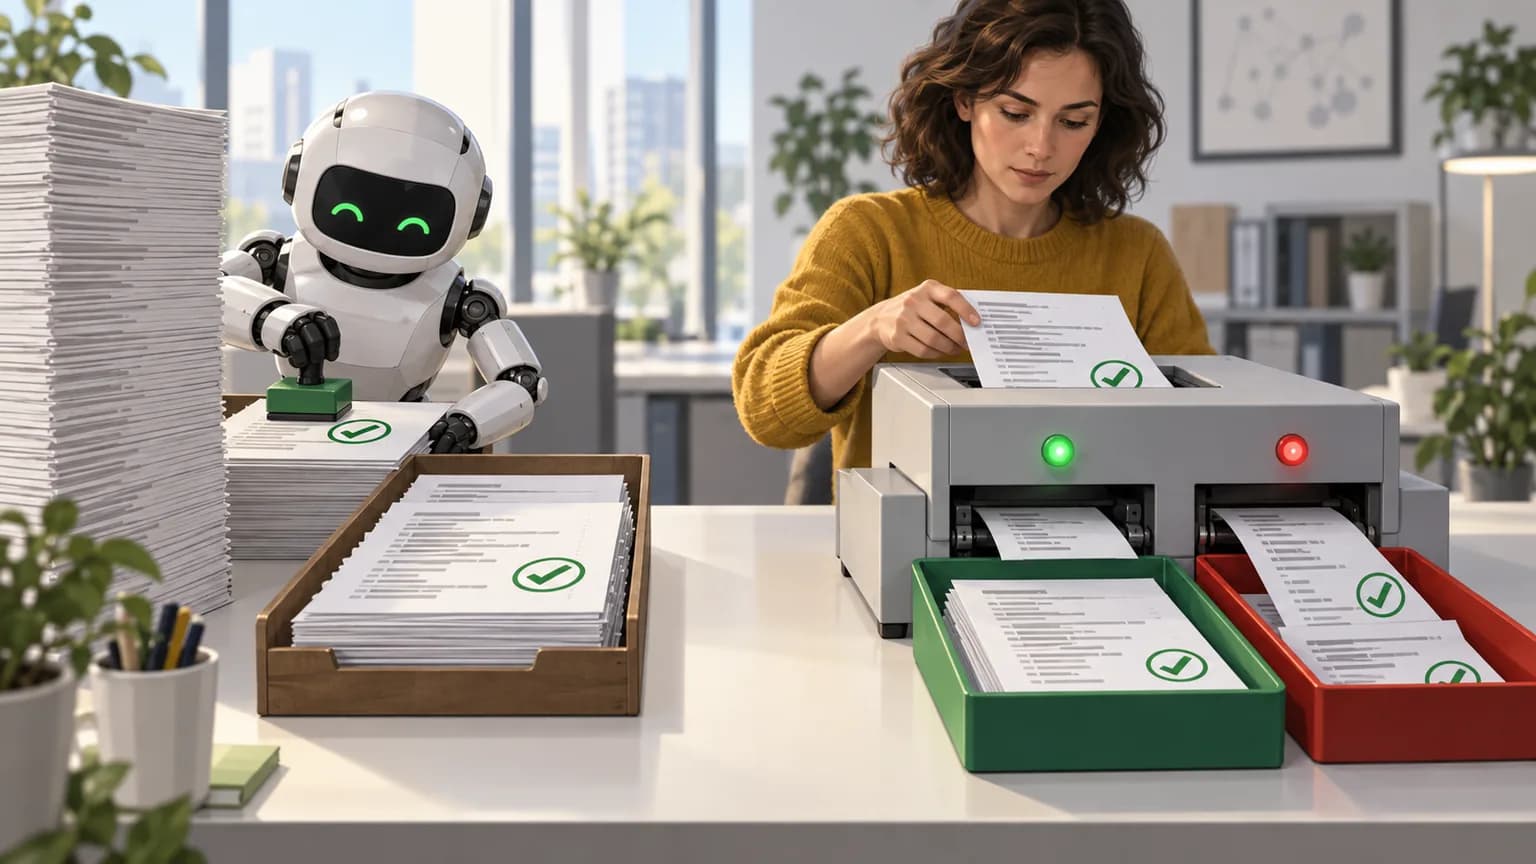
Can you trust an AI model’s confidence in its own answer? Not as the only quality filter. In an experiment published on October 15, 2026, three language models solved 20 Python tasks and labeled all 179 answers as “confident,” even though four solutions failed hidden tests. The confidence label that the model writes in the same answer did not distinguish correct code from incorrect code. Research shows that self-assessment can become a useful signal, but only after calibration on your own data. External checks catch errors: tests, rules, a second pass, and human review based on risk level.
Prepared by AIrassvet October 16, 2026 based on the developer’s experiment published on Habr on October 15, 2026, and on two studies: Kadavath et al. (2022) on models’ ability to evaluate their own answers and Kalai et al. (2025) on the causes of hallucinations. It is intended for leaders implementing AI in business processes, product owners, and IT and QA leads. We did not repeat the experiment or measure model calibration: the verification scheme and routing rules are the editorial team’s methodology. AIrassvet is not affiliated with the experiment author or the researchers; the section at the end of the article describes the publisher’s services.
Contents
- In Brief
- What the 179-answer experiment showed
- What cannot be concluded from the experiment
- What research says about model self-assessment
- Why models do not say “I don’t know”
- What to use instead of self-assessment: a verification ladder
- How to check whether the confidence signal works for you
- Frequently Asked Questions
- Original sources and verification method
In Brief
- 179 out of 179 answers were “confident.” None of the three models chose the “not confident” option even once, although it was in the instructions.
- There were errors, and they were simple. Four solutions (about 2.2%) failed the tests: an incorrect parse of a standard date, lost
..in the path, and an off-by-one unit sign. - A filter based on the label would have missed every error. If only answers labeled “not confident” were sent for review, the queue would have stayed empty.
- Self-assessment is not useless, but it needs calibration. The 2022 study shows that probabilistic self-assessment can work on some tasks, but transfers less reliably to new ones.
- More reliable are external checks: automated rules and tests, a second pass, source verification, and human review where the cost of an error is high.
What the 179-answer experiment showed
Model self-assessment is the model’s statement about how confident it is in its own answer: in words (“confident”), as a score, or as a probability.
The developer tested a simple idea: if you ask a model to honestly say at the end of its answer whether it is confident in the code, can you use that label to screen out bad solutions in advance without running tests (Habr, 10/15/2026).
Experiment conditions:
- 20 tasks, each requiring one Python 3.9 function without third-party libraries; the prompts intentionally included easy-to-miss details;
- 247 hidden tests that the models did not see; a task counted only if it passed all of its tests;
- the models could not run code and in the same answer wrote the string
CONFIDENCE: SUREorCONFIDENCE: UNSURE, with “confident” allowed only if the model was sure the code would pass strict hidden tests; - 3 models × 20 tasks × 3 runs; the final sample contained 179 answers, with one timing out.
Results:
| Model (as listed in the API) | Answers | Passed tests | “Confident” | “Not confident” | “Confident,” but wrong |
|---|---|---|---|---|---|
| gpt-6.1-sol | 60 | 60 | 60 | 0 | 0 |
| claude-haiku-5-5 | 60 | 59 | 60 | 0 | 1 |
| glm-5.3-flash | 59 | 56 | 59 | 0 | 3 |
| Total | 179 | 175 | 179 | 0 | 4 |
Which errors were labeled “confident”:
- the date-difference function sliced the string
YYYY-MM-DDas if there were no hyphens and failed on ordinary dates — even though the model’s comments carefully discussed rare edge cases; - path normalization turned
../../ainain two out of three repeats, and the code was preceded by the correct comment saying that..should be preserved; format_bytes(1024)returned1.0 MiBinstead of1.0 KiB— an off-by-one labeling error; 11 of the task’s 14 tests failed.
The author’s main takeaway: using such a label as permission to skip tests is not acceptable — at least when the evaluation happens in the same response, without running code and without a second pass.
What you cannot conclude from the experiment
The author also lays out the limitations in detail, and for business they matter no less than the result:
- You cannot rank models. There were only 20 tasks, and three repeats of the same task are not three different tasks.
- Only one question format was tested. Other phrasings, asking about confidence in a separate message, and the ability to run code were not tested.
- API-side conditions were not equal. Requests went through a third-party aggregator; the actual backend behind each model name was not verified, and temperature and seed were not set.
- The tests were not perfect. The tasks, tests, and gold answers were prepared with Claude; the checker script is fairly lenient.
- The accounting is incomplete. Six unlabeled answers (empty and truncated) were re-requested, and one more model’s run fell apart and did not make it into the table.
So the correct conclusion is narrow: in this setup, a verbal confidence label in the same response did not distinguish correct code from incorrect code. This is not a measurement of model calibration overall.
What research says about model self-assessment
The picture is more complex than “models are always overconfident.” In the paper “Language Models (Mostly) Know What They Know” (Kadavath et al., 2022), it is shown that:
- large models are well calibrated on multiple-choice questions and true/false questions if they are prompted in the right format;
- you can ask the model to first give an answer and then estimate the probability that it is correct (P(True)), and on different tasks this gives encouraging results;
- self-assessment improves if the model first sees several of its own answer variants;
- the prediction of “do I know the answer” (P(IK)) works, but is less well calibrated on new task types.
Calibration is the alignment between stated confidence and actual accuracy: if a model says it is “80% confident,” it should be right in about 80% of such cases.
| Signal type | How it is obtained | What to expect |
|---|---|---|
| Verbal label in the same response (“confident / not confident”) | Prompt instruction | In the October 2026 experiment — the same label on all responses |
| Probability estimate after the answer (P(True)) | Separate self-check step | According to the 2022 study — useful on some tasks, requires calibration checks |
| Consistency across multiple answers | Multiple generations and comparison | Helps self-assessment, but increases cost |
| External verification | Tests, rules, sources, human review | Does not depend on the model’s opinion of itself |
The practical takeaway: you cannot trust self-assessment by default, but you can use it as an additional signal if you have verified on your data that it separates correct answers from incorrect ones.
Why models do not say “I don’t know”
One explanation is given in the paper “Why Language Models Hallucinate” (Kalai, Nachum, Vempala, Zhang; September 2025): training and evaluation procedures reward guessing more than admitting uncertainty. Models are optimized to be good test takers, and on most benchmarks it is more advantageous to guess than to answer “I don’t know.” The authors propose changing the evaluation system in popular benchmarks that penalize uncertain answers.
For business, the simple rule is this: if the system rewards only “correct” answers and does not encourage abstention, the model will answer confidently even when it does not know. An “I don’t know” refusal must be explicitly allowed in the instructions, counted in the evaluation, and not treated as an error.
We wrote in detail about how errors appear in knowledge base search systems in the article “RAG Accuracy and Hallucinations”.
What to use instead of self-assessment: a verification ladder
Our editorial method: checks are arranged from cheap and automated to expensive and manual, and the depth depends on the cost of an error.
| Level | What it checks | Examples | When it is required |
|---|---|---|---|
| 1. Format and rules | Structure and allowed values | JSON schema, required fields, amount and date ranges | Always, if the response goes into another system |
| 2. Execution and tests | Whether the result works | Automated tests for code, checksum calculation, final reconciliation | For code, calculations, and data transformation |
| 3. Source verification | Whether the facts are confirmed | A link to a document in the knowledge base, quote matching | For answers to customers and employees based on documents |
| 4. Second pass | An independent look at the answer | A separate review request, with another model acting as the checker | For complex or ambiguous cases |
| 5. Human | A substantive decision | Sample review, action confirmation | For money, legally significant, and irreversible actions |
Routing rules:
- Tie the review to the risk, not to the model's confidence. An answer about office hours and a payment order require different levels of control, even if the model is equally “confident” about both.
- The agent should be able to check itself. If the agent writes code, let it run tests in an isolated environment; if it does calculations, give it a calculation tool.
- Sample human review even if all automated checks pass. Automated tests only catch what they were designed to catch.
- Log the confidence label and the review result. This data helps answer whether the self-assessment is worth considering at all.
How to organize review of code written with AI is covered in the article “Code Audit After Vibe Coding”and how to test an agent before launch is covered in the piece about the sandbox for an AI agent.
How to check whether the confidence signal works for you
If you want to use the model's self-assessment for routing—for example, sending only “uncertain” answers to a human—first test it on your own data (editorial method):
- Collect 50–100 real tasks with a known correct answer or a way to verify it.
- Get answers and the confidence signal in the same way you plan to use them in production.
- Verify each answer externally: with tests, by cross-checking a document, or with an expert.
- Build a simple table: how many errors are in the “confident” group and in the “uncertain” group.
- If the error rate is the same in both groups or almost all answers are “confident,” the signal is useless for routing.
- Repeat the check whenever you change the model, prompt, or task type—according to a 2022 study, calibration does not transfer well to new tasks.
The same approach applies to model selection: your own task set is more reliable than public leaderboards. More details in the article “Build Your Own Benchmark for Choosing an LLM”.
Frequently asked questions
Can you trust AI confidence in its own answer?
Not as the only filter. In an October 2026 experiment, all 179 answers were labeled “sure,” even though four were wrong. Self-assessment can be a useful additional signal only after it has been tested on your own tasks.
Why are language models almost always confident?
One explanation: training and popular tests reward guessing more than admitting uncertainty. Models are optimized to give an answer, not to say “I don't know,” unless refusal is explicitly allowed and counted in evaluation.
What is model calibration?
It is the match between stated confidence and actual accuracy. A well-calibrated model's answers with 80% confidence are correct about 80% of the time. Calibration is measured on a task set with known answers.
What should replace model self-assessment?
External checks: rules and schemas for format, tests and calculations for code and numbers, source verification for facts, a second pass for complex cases, and human review for risky actions.
Does asking the model “are you sure?” in a separate message help?
This was not tested in the experiment. Studies show that a separate self-check step and comparison of multiple answers can improve self-assessment, but the result needs to be measured on your own tasks.
Should AI answers be checked if there are few errors?
Yes. In the experiment, errors were about 2.2%, but a filter based on self-assessment would have let all of them through. The depth of review should depend on the cost of an error, not on the average error rate.
Primary sources and review method
Method: on October 16, 2026, we read the experiment on Habr, extracted the conditions, results table, error analysis, and limitations, then cross-checked the conclusions against the abstracts of two studies on arXiv. AIrassvet did not perform its own calibration measurements; the review ladder, routing rules, and the order for checking the signal are the editorial method.
- Habr, 10/15/2026: the experiment “all 179 answers were SURE” — conditions, results for three models, four errors, limitations.
- arXiv:2207.05221: Kadavath et al., “Language Models (Mostly) Know What They Know,” 2022 — calibration, P(True), P(IK).
- arXiv:2509.04664: Kalai, Nachum, Vempala, Zhang, “Why Language Models Hallucinate,” 2025 — why training and evaluation reward guessing.
Limitations: the experiment was small (20 tasks, three models, one prompt variant, a third-party API aggregator); the studies evaluated different models and tasks, so their conclusions cannot be directly transferred to a specific model in your process.
How AIrassvet helps you build AI answer verification
AI reliability in a process is determined not by the model, but by how the checks around it are set up. On the AIrassvet website the directions directly relevant to this task are described:
- testing AI solutions before launch: functional scenarios and a task set with known answers for measuring errors;
- RAG systems based on the company's knowledge base, where the answer includes a link to the source document so it can be checked;
- building AI agents with self-check tools—running tests and calculations—and human confirmation of risky actions;
- process audits: where the cost of an error is high and what level of control is needed at each step.
The first step is to choose one process where AI is already in use or planned, describe the current method of checking the result, the data sources, the constraints, and the acceptable error threshold.
Bottom line: trust checks, not confidence
The experiment with 179 answers showed a simple thing: a model can write “confident” under incorrect code, even when it is directly asked to use that label only when fully certain. The research adds a nuance: probabilistic self-assessment can be made useful, but only after checking calibration on your own tasks.
So in workflows, model confidence is at best an additional signal. Quality is ensured by external checks chosen according to the cost of an error: rules and tests, source verification, a second pass, and a human where an error is expensive.