If Claude prompt caching isn’t returning cache reads, first separate two cases: the prefix is not being written at all, or it is being written again on every request. These are distinguished by the fields cache_creation_input_tokens and cache_read_input_tokens in usage. Then check the length of the shared portion, the placement of cache_control, content matching, and the interval between requests.
Prepared by AIrassvet based on official Anthropic documentation, verified on October 21, 2026. It is intended for the integration developer and the business process owner who reprocesses requests with one long instruction. This refers to the direct Claude API: Bedrock rules, other providers, and Claude app settings cannot be automatically transferred here.
This is a documented troubleshooting workflow, not a report on our own Claude deployment. The support scenario and numbers below are illustrative; we did not measure real savings, compatibility with your SDK version, or account availability.
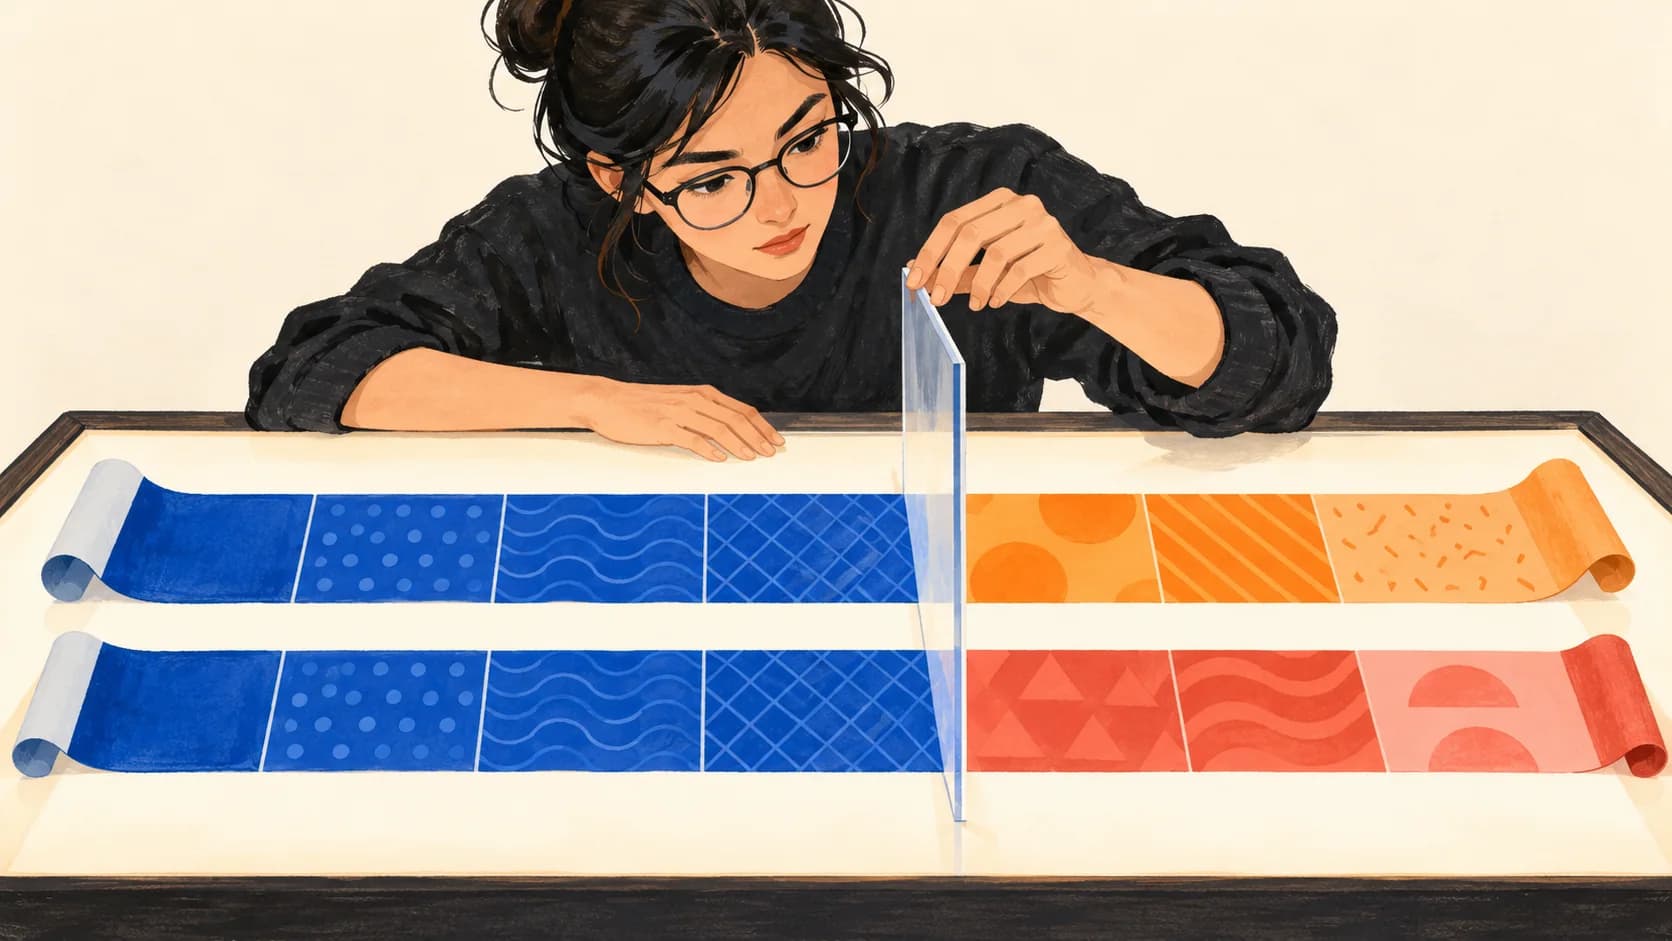
*The illustration shows a shared prefix and a changing request suffix; it is not the Claude interface and not a test result.*
Contents
- What exactly should be reused
- Symptom: both counters are zero
- Symptom: there is a write every time, but no reads
- Symptom: it works sometimes, then disappears
- Symptom: a long conversation loses the old write
- How to confirm the cause and verify the fix
- Why a cache hit does not necessarily mean savings
- How AIrassvet helps analyze repeated context processing
- Where to start with the fix
What exactly should be reused
Prompt caching is the reuse of the already processed beginning of a request, or prefix. It is not returning a saved answer to a similar question. In Claude, identical blocks up to the selected boundary inclusive matter; semantic similarity is not enough. The prefix is formed in this order: tool definitions tools, system instructions system, then message history messages. Source: Anthropic caching mechanism.
Imagine an equipment vendor’s support desk. Every request is processed with the same classification rules, category descriptions, and examples. The customer text changes. The useful shared prefix ends here after the rules and examples, before the specific request.
If the date, ticket ID, or personal context appears at the start of the instruction, the later identical paragraphs no longer form the original prefix. You can move allowed variable data closer to the end only while preserving meaning and access rights: you cannot combine different customer instructions just to force a cache hit.
Symptom: both counters are zero
First, open the full usage data in the response. In streaming output, these fields are in the message_start event. For a regular text request, look at three input components:
| usage field | What it shows | How to use it for diagnosis |
|---|---|---|
cache_creation_input_tokens |
Tokens written to cache | A nonzero value confirms a write, not savings |
cache_read_input_tokens |
Tokens read from cache | A nonzero value confirms reuse in this request |
input_tokens |
Regular input tokens outside cache reads and writes | This is not the full input when caching is enabled |
The full input is the sum of these three values. If both read and write are zero, the cache was not used in this request; one likely reason is that the cacheable portion is too short. This is a diagnostic hypothesis, not a definitive explanation for every zero. Source: usage fields and limits.
Check whether caching is enabled and whether the prefix reaches the minimum length for your specific model. For example, current documentation lists 512 tokens for Claude Sonnet 5.5 and 4096 for Claude Haiku 4.5 in the direct API. A short prefix with cache_control may be processed without cache and without an error. There is no universal threshold for all Claude models. Source: minimum length.
You need to count the shared portion up to the boundary, not just the entire request. A long email after a short instruction does not by itself make that instruction cacheable. The token counting endpoint helps estimate size, but it does not perform caching and does not prove a hit. Count the prepared shared context for the selected model, then check the actual usage fields when creating the message. Source: token counting.
Do not add meaningless paragraphs just to reach the threshold. If there is little genuinely useful shared content, keep the request normal: the cost of bloating the context and maintaining it also matters.
Symptom: there is a write every time, but no reads
For independent requests, check whether the boundary ended up after variable text. Anthropic writes the prefix at the cache_control position. The backward search looks for previously written positions; it does not automatically create a separate write at the end of any stable section. So placing the marker after changing request content can produce a new write without reusing the shared rules. Source: prefix matching and a common mistake.
For our hypothetical scenario, the fix looks like this:
- Separate the fixed classification rules from the user message content and the time it was received.
- Place the stable instructions and examples in fixed blocks; keep the same tool definitions before them.
- Add an explicit
cache_controlto the last stable block. - Send the new request after this boundary and compare sequential request
usage.
Below is a sample request layout, not a ready-to-send API body and not the result of a completed test. The label “cache boundary” refers to the position of the parameter on the last stable block, not text that should be sent to the model:
tools: unchanged tool definitions
system: general rules + categories + examples [cache boundary]
messages: the specific request text
The parameter itself on this block looks like this:
{"cache_control": {"type": "ephemeral"}}This fragment needs to be included in a complete request in your integration. The size of the shared prefix, the model, and the actual responses remain part of your own testing.
Automatic caching with cache_control at the top level is convenient for a growing conversation: the boundary moves along with the history. For independent requests with different endings, an explicit boundary on shared rules gives clearer control. Choose based on the structure of the task, not on the idea that “automatic is always better.” Source: automatic and explicit caching.
Symptom: sometimes it works, sometimes it disappears
First, compare the request start times. The standard TTL — cache time to live — is 5 minutes; reading refreshes it. According to the documentation, the countdown starts from the beginning of the request that wrote or read the entry, not from the end of the response. If generation took almost the entire interval, the user’s pause after the response may be enough for the entry to expire. Source: cache time to live.
If the shared context repeats less often, consider ttl: "1h" inside cache_control. An hourly entry is billed differently; it makes sense to evaluate a longer term based on repetition frequency and current rates. It does not fix a changing prefix. Do not add regular empty requests just to keep the cache alive without first calculating their cost and necessity. Source: hourly TTL.
The second cause is a parallel cold start. The entry becomes available after the first response begins. If you send the whole batch at once, the first requests may not read an entry that has not appeared yet. For a diagnostic check, first send one request, wait for the response to start, then launch the others. This is a documented condition for when the entry becomes available, not a guarantee of a 100% hit rate. Source: parallel requests.
The third cause is a configuration change. Compare one model, one workspace, the same tools, system, tool_choice settings, thinking, and output_config.effort. Changing a tool at the beginning affects the following prefix levels. Do not turn off a needed check or tool just for the sake of caching: sometimes a miss is the normal cost of an necessary change. Source: invalidation.
Symptom: a long conversation loses the old entry
If the history is growing and the beginning stays the same, check the distance to the previous recorded position. The documentation describes a backward search window of up to 20 positions to the boundary, counting the boundary itself as first. In the direct Claude API, consecutive tool_use blocks count as one position, as do consecutive tool_result blocks; simply counting the number of function calls is incorrect. Source: search window.
When the previous entry falls outside the window, adding an extra explicit boundary closer to the needed point may preserve the available reuse path. It should be placed so that an entry has time to appear there. Adding a marker retroactively does not create a cache that already existed in past requests.
This is a separate case of a growing history. For independent requests with a stable instruction, first move the boundary before the variable text; do not complicate the setup with multiple markers without identifying the cause.
How to confirm the cause and verify the fix
In the direct Claude API there is cache diagnostics: a comparison of the structure of two requests. According to the current documentation, the first request should include diagnostics with previous_message_id: null, so that the diagnostic fingerprint is preserved. In the next request, you specify the id of the previous response in diagnostics.previous_message_id. If the object is missing in the first request, there is no fingerprint for this kind of comparison. Source: order of enabling diagnostics.
Diagnostics help isolate differences in the model, tools, system text, or history. At the same time, the absence of a difference does not prove that the cache was read: structural comparison is independent of whether there was an actual hit. The final sign of reuse is cache_read_input_tokens in the response. TTL expiration also cannot be disproven by a single matching structure. Source: diagnostics together with usage.
The suggested validation check is on two anonymized or synthetic requests with the same rules:
- Record the model, workspace, tools, and the exact version of the shared text. Exclude unrelated configuration changes from the comparison.
- Run the first request with the selected boundary; save
usage, the start time, and the response ID. The reading may be nonzero if this prefix has not yet been warmed up. - After the first response starts, run the second one within the TTL. Change only the request text after the shared boundary. The expected sign of successful reuse is a nonzero read of the shared portion.
- If no read appears, go back to the prefix length, boundary, structure, and timing. Do not declare the fix based on a single API error disappearing.
- Check that the classification still matches the rules. A good cache result by itself says nothing about the correctness of the answer.
This is a plan for your environment; it was not run here. Do not store API keys or customer text in public logs; a single ID and numbers are often enough for an initial comparison. General observability principles are covered in the article on monitoring LLMs and AI agents.
Why a cache hit still does not mean savings
A hypothetical second request returned 3,000 tokens read, 0 written, and 200 normal input. Full input is 3,200 tokens, and the share of input read is 3,000 / 3,200 = 93.75%This is an arithmetic example of how to interpret the counters, not our result and not a discount on the entire bill.
Pricing also depends on writing, response generation, and the rates of the selected model. Reading a long prefix can be paired with an expensive long answer. If repetition is rare, the cost of the initial write may not pay off. That is why you should compare total spend for the same number of useful requests at the same quality requirements, not just the read share. Source: caching pricing.
Broader solutions—model routing, context length, and cost allocation—are covered in the material on cost control as token counts grow. Here the task is narrower: explain the specific miss and confirm reuse of the shared portion.
How AIrassvet helps break down repeated context processing
As part of an AI process and integration audit, you can set three specific tasks: identify the shared context and variable request data; determine which technical metrics are needed to verify reuse; and test integration and classification quality after changing the request structure. These are tasks in the areas of data preparation, integration, and testing, listed on the AIrassvet website.
The first step is to choose one request stream, describe the initial costs, data sources, constraints, and the readiness criterion. The result of this analysis should help you decide whether to change the structure or keep the current approach; the savings percentage is not known in advance. Discuss the task.
Where to start the fix
Start with a pair of real usage, not with increasing the TTL. Two zero counters point to enabling the cache and the length of the shared portion; constant writes without reads point to a changing prefix and boundary; irregular misses point to timing, parallelism, and configuration. In a long history, also check the search window.
Readiness is confirmed by a read of the shared portion in an appropriate repeat request and by maintaining task quality. After that, calculate the total process cost. That is how caching becomes a verifiable integration change, not a promise of a discount from one parameter.