A vector database is a storage system that keeps texts, images, and other objects as vectors (sets of numbers that describe meaning) and can quickly find the ones most similar to a query. Thanks to it, an AI assistant can find the right policy clause even when an employee phrases the question differently. It is the foundation of RAG systems, semantic search, and recommendations. At the same time, a vector database does not “understand” documents on its own: search quality depends on the embedding model, document chunking, access-control filters, and index settings.
Prepared by AIrassvet October 19, 2026 for executives, product owners, and IT managers who hear about “vector search” in AI projects and want to understand what is behind it. The explanation is based on OpenAI, pgvector, and Qdrant documentation, as well as academic papers on HNSW, the Faiss library, RAG, and reconstructing text from embeddings. We did not run our own speed or quality tests for this article.
Contents
- At a Glance
- Definition and Scope of This Article
- What Is an Embedding?
- How Vector Search Works: Five Steps
- Exact and Approximate Search: HNSW and IVFFlat Indexes
- Filters, Metadata, and Access Rights
- Hybrid Search: Meaning Plus Exact Words
- Where Vector Databases Are Used in Business
- A Dedicated Vector DB or PostgreSQL with pgvector
- Limitations and Risks
- Glossary
- FAQ
- Primary Sources
At a Glance
- A vector database searches by meaning, not by matching words. Each object is converted into a vector, and the closeness of vectors reflects the closeness of meaning.
- Vectors are created by a separate embedding model. For example, OpenAI's text-embedding-3-small model returns vectors with 1,536 numbers, while text-embedding-3-large returns 3,072.
- Approximate search is used for speed. Indexes like HNSW trade a small amount of accuracy for speed; pgvector searches exactly by default, but more slowly.
- Access-control filters need to be designed separately. With approximate search, a filter may return fewer results than requested.
- Embeddings are not anonymization. A 2023 study was able to reconstruct 92% of short texts exactly from their vectors.
Definition and Scope of This Article
A vector database stores vectors along with the original objects and their metadata, and answers the question, “Which records are closest to this vector?” A traditional database answers questions like “Find contracts with number 145” — it compares values exactly. A vector database answers, “Find documents about the same thing as this question,” even if they share no words.
The term “vector database” is used both for specialized systems (Qdrant, Milvus, Weaviate) and for extensions to familiar DBMSs, such as pgvector for PostgreSQL, as well as search libraries like Faiss that are embedded into an application. They all follow the same principle, but differ in operational convenience, filtering, and scale.
This article explains how a vector database works and where it is useful. We do not compare specific products by speed, provide benchmarks, or break down the full RAG architecture — that is covered in the article “RAG System for Business”.
What Is an Embedding?
An embedding is a vector, meaning a list of numbers a model uses to describe the meaning of text, an image, or another object. OpenAI's documentation defines it this way: an embedding is a vector of floating-point numbers, and the distance between two vectors measures how related they are — the smaller the distance, the stronger the connection.
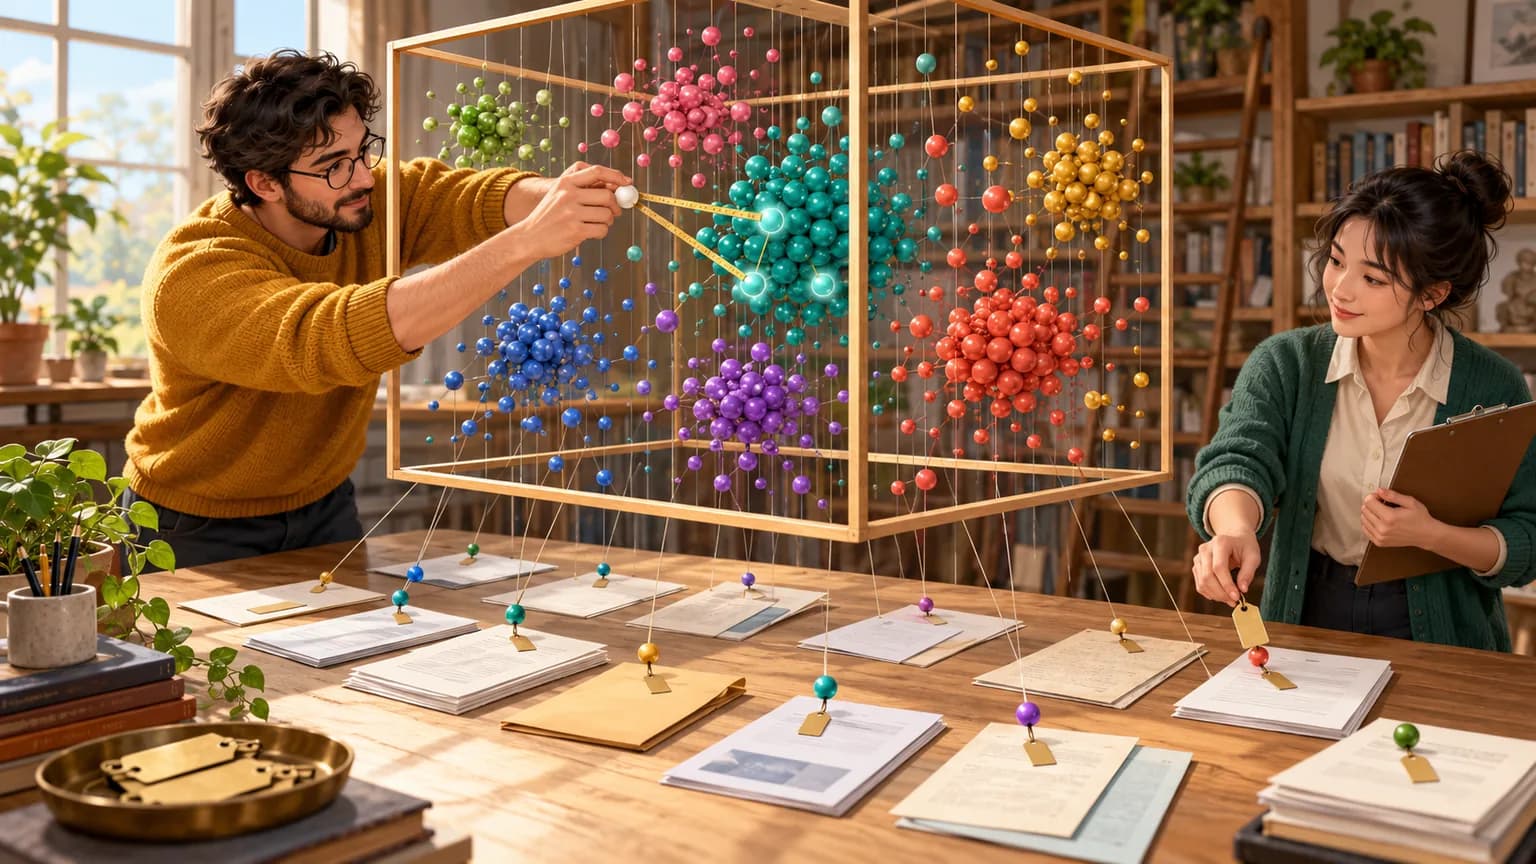
The easiest way to picture it is as a map where phrases with similar meaning are placed near each other. “How do I request vacation time?” and “annual leave policy” will be neighbors, even though they use different words. The difference is that this map has not two dimensions but hundreds or thousands: text-embedding-3-small has 1,536, and text-embedding-3-large has 3,072.
This leads to two practical conclusions. First, vectors from different models are not compatible: you can only compare vectors created by the same model. Second, search quality depends heavily on the embedding model and on how well it understands the company’s language and terminology.
How Vector Search Works: Five Steps
- Chunking. Documents are split into fragments — paragraphs, sections, cards. If a fragment is too large, the meaning gets blurred; if it is too small, context is lost.
- Vectorization. The embedding model converts each fragment into a vector. Along with the vector, the fragment text and metadata are stored: source, date, department, access level.
- Indexing. The database builds an index that avoids comparing the query against every vector one by one.
- Query. The user’s question is vectorized by the same model, and the database looks for the nearest vectors — usually by cosine similarity, which OpenAI, for example, recommends.
- Using the result. The retrieved fragments are shown to the user as search results or passed to the language model so it can answer based on them. The second option is RAG: in the original paper by Lewis et al. (2020), the model accessed a dense Wikipedia vector index through neural retrieval.
Between steps 4 and 5, reranking is often added — a second, more precise pass over the retrieved candidates. We covered when it pays off in the article “Reranker in RAG”.
Exact and Approximate Search: HNSW and IVFFlat Indexes
Nearest neighbors can be found exactly by comparing the query against every vector. That is how pgvector works by default: the documentation says exact search gives perfect recall. But with millions of vectors, a full scan becomes slow, so approximate nearest neighbor (ANN) indexes are used. They find almost all nearest neighbors much faster, sacrificing a small amount of recall.
The most common approach is HNSW (Hierarchical Navigable Small World), described by Y. Malkov and D. Yashunin in 2016–2018. The vectors are linked in a multilevel graph: search starts on sparse upper levels and moves down to denser ones, and the authors claim logarithmic scaling in complexity. The second common type is IVFFlat: vectors are pre-grouped, and search is performed only within the nearest groups.
| Parameter | Exact Search | HNSW | IVFFlat |
|---|---|---|---|
| Result completeness | Complete | Nearly complete, tunable | Nearly complete, tunable |
| Query speed at scale | Low | High | Medium |
| Index build time | Not needed | Longer | Faster |
| Memory | Minimal | Higher | Less |
| When to choose it | Small datasets, benchmark validation | The default choice for fast responses | Limited memory, frequent reindexing |
*The ratios in the table are based on pgvector documentation; the exact figures depend on the data and settings and were not measured in this article.*
pgvector also has a practical limit: you can index vector-type vectors up to 2,000 dimensions and halfvec-type vectors up to 4,000. That means 3,072-dimensional text-embedding-3-large vectors in pgvector will require half precision or dimensionality reduction.
Filters, metadata, and access control
In business, you almost never need a “search everything” approach. A sales rep should not see HR documents, and an answer about pricing should rely on the current price list, not last year’s. To do this, metadata is attached to each vector — in Qdrant this is called payload and is stored as arbitrary JSON — and filtered during search. Qdrant’s documentation explains why this matters: not all object properties can be expressed in an embedding.
There is a catch here. The pgvector documentation warns that in approximate search, the filter is applied after scanning the index. An example from the docs: if 10% of rows match the condition and the hnsw.ef_search parameter is 40 (the default), then on average only about 4 matching rows will be returned. For this reason, pgvector 0.8.0 introduced iterative index scans, and specialized databases offer their own filtering mechanisms. You should test filter behavior on your own data before launch.
Access control is more reliable when applied before or during search, not after response generation: if content from another department has already entered the model’s context, it can leak into the answer.
Hybrid search: meaning plus exact words
Vector search is good at finding paraphrased questions, but it can miss exact values: SKUs, contract numbers, rare surnames, error codes. Traditional full-text search, on the other hand, is precise with words and blind to meaning. That is why hybrid search is often used: both are run and the results are combined.
Qdrant describes this approach as combining dense vectors (meaning) and sparse vectors (exact words), and for merging result lists it offers the RRF (Reciprocal Rank Fusion) method. It promotes documents that appear near the top of several lists at once. We covered what this looks like in a product catalog search example in the article “Smart Search for an Online Store”.
Where vector databases are used in business
- Company document assistant (RAG). Policies, contracts, procedures, and the support knowledge base become the source of answers for an AI assistant — more details in the article on a corporate knowledge base with an AI agent.
- Semantic search in a catalog. A shopper types “jacket that won’t let the wind through,” and finds windproof models.
- Similar support requests and duplicates. A new support ticket is compared with resolved ones to suggest a ready-made solution to the agent or identify duplicates.
- Recommendations. Products, articles, or courses that are semantically close to what the person has already viewed.
- Classification and routing. The request is assigned to the category whose vector it is closest to — without training a separate classifier at the start.
- Image search. With multimodal embeddings, you can search for similar product photos, drawings, or defects.
In all cases, the vector database is infrastructure. The business impact depends on how search quality is measured; we described the methods in the article “RAG Accuracy and Hallucinations”.
Dedicated vector DB or PostgreSQL with pgvector
| Situation | What is usually more sensible | Why |
|---|---|---|
| The data is already in PostgreSQL, volume is moderate | pgvector | One database, familiar transactions, backups, and permissions |
| You need complex filters, hybrid search, separate scaling | Specialized vector DB | Built-in filtering and result-merging mechanisms |
| Search is embedded in the application, data is static | A library like Faiss | No separate server, full control over the index |
| A pilot on a small knowledge base | The simplest option among the tools you already use | It matters more to validate answer quality than to choose the “best” database |
*The table is the editorial team’s methodology, summarizing pgvector, Qdrant, and Faiss documentation; we did not run benchmarks.*
The decision almost always comes down not to speed, but to operations: who will update the index when documents change, how access rights will be carried over from the source systems, and how the data will be reindexed when the embedding model changes.
Limitations and risks
- Changing the embedding model means reindexing. Vectors from different models are not comparable, so when you switch to a new model, the entire database must be vectorized again. Store the source chunks, not just the vectors.
- Outdated data. The database only knows what was loaded into it. Without regular updates, the assistant will confidently cite a policy that has already been revoked.
- Exact values. Numbers, SKUs, and codes can be missed by pure vector search — hybrid search or filters are needed.
- Embeddings do not anonymize data. Morris et al. (2023) reconstructed about 92% of 32-token texts exactly from their embeddings, and on medical records — full patient names. Protect vectors containing personal data the same way you protect the original texts.
- There is no guarantee of a correct answer. A vector database finds what is similar, not what is correct. If the answer is not in the documents, it will still return the closest match — and the model may build an inaccurate answer on top of it.
Glossary
- Vector — an ordered set of numbers; in a vector database, it describes an object’s meaning.
- Embedding — a vector produced by a model from text, an image, or another object.
- Dimensionality — the number of numbers in a vector, for example 1536.
- Cosine similarity — a measure of how similar two vectors are based on the angle between them.
- ANN (approximate nearest neighbor) — approximate nearest-neighbor search.
- HNSW — a multilevel graph-based index for fast approximate search.
- IVFFlat — an index that groups vectors and searches within the nearest groups.
- Recall — the share of truly nearest objects that the search found.
- Metadata (payload) — additional record fields: source, date, access permissions.
- Hybrid search — a combination of vector and full-text search.
- RRF — a method for combining multiple result lists based on rank positions.
- RAG — an approach in which a language model answers using retrieved document excerpts as context.
Frequently asked questions
Is a vector database the same as RAG?
No. RAG is an approach in which a language model answers using retrieved documents as context. A vector database is one way to find those documents. RAG can also use full-text search, and a vector database is used not only in RAG, but also in catalog search, recommendations, and duplicate detection.
Do you need a vector database if there are only a few documents?
Not necessarily a separate one. For a small knowledge base, exact search in pgvector or a library in the application will be enough, and sometimes simple full-text search is sufficient. A separate vector DB makes sense when volume, filtering requirements, and speed demands grow, or when you need hybrid search.
Can personal data be stored in a vector database?
Yes, but it must be protected the same way as the source data. A study by Morris et al. (2023) showed that text can be largely reconstructed from an embedding. That means vectors are subject to the same access, storage, and processing-location requirements as the documents they were derived from.
What happens if you switch the embedding model?
You will need to re-embed all documents and rebuild the index: vectors from different models are not compatible. That is why you should store the original excerpts and metadata alongside the vectors and test the new model on a set of real queries before moving your entire database to it.
Why doesn't vector search find a contract number?
Because it searches by meaning, while a number is an exact value with no semantic load. For queries like that, you add full-text search or a filter on a metadata field, and then combine the results, for example with RRF. This hybrid approach is described in the Qdrant documentation.
Primary sources
Documents and articles checked on October 19, 2026:
- OpenAI: Vector embeddings — definition of an embedding, dimensionality, cosine similarity.
- pgvector on GitHub — exact search by default, HNSW and IVFFlat, dimensionality limits, filtering.
- Malkov, Yashunin. HNSW, 2016–2018 — a multilayer graph algorithm.
- Douze et al. The Faiss library, 2024 — a vector search library.
- Qdrant: Filtering and Qdrant: Hybrid queries — metadata, hybrid search, RRF.
- Lewis et al. Retrieval-Augmented Generation, 2020 — the original paper on RAG.
- Morris et al. Text Embeddings Reveal (Almost) As Much As Text, 2023 — reconstructing text from embeddings.
Figures are based on data from the authors and developers; we have not independently verified them.
How AIrassvet helps implement vector search
A vector database is useful when it is clear which questions it should answer, from which sources, and for whom. On the AIrassvet website you can find the areas related to this task:
- RAG systems built on a company knowledge base: document preparation and chunking, vectorization, search with access-rights filters;
- deploying language models on the client’s servers if documents and their vectors cannot be sent to an external service;
- process audits, data preparation, and search-quality testing using real employee or customer questions.
The first step is to choose one process where people spend time searching for information, describe the current result, document sources, access restrictions, and the criterion by which the search will be considered successful.
Bottom line: a vector database is search by meaning, not a ready-made answer
A vector database stores objects as vectors and quickly finds semantically similar ones — which is why it powers RAG assistants, catalog search, and recommendations. But its quality is determined not by the database itself, but by the embedding model, document preparation, access filters, and regular updates.
If you are planning a vector search project, start with a set of real questions and test against it, and choose between pgvector and a separate DB based on operational requirements. And remember that vectors containing personal data require the same protection as the documents themselves.