For AI search to answer from a paper archive, scanning pages is not enough. You need to select documents based on retention periods, prepare the paper, scan at a resolution of at least 300 dpi, check the recognized text, fill in metadata and access rights, and then test search against real employee questions. Below is a copyable seven-step checklist with owners and “done” criteria.
Prepared by AIrassvet October 25, 2026 for executives, office managers, records managers, and IT specialists who want to connect a paper archive of contracts, acts, letters, or technical documentation to enterprise AI search. The checklist is based on Rosarchive’s List of Standard Administrative Archival Documents, Tesseract OCR engine documentation, and the Library of Congress description of the PDF/A format. The sequence of steps and criteria are our editorial method, not a standard. This is not legal advice: decisions about retention periods and destruction of originals should be made with legal counsel and the archive owner.
Contents
- Quick Overview
- Who this checklist is for and what it does not cover
- What You Need Before You Start
- Step 1. The goal and the questions the search must answer
- Step 2. Inventory and document selection
- Step 3. Preparing paper for scanning
- Step 4. Scanning settings and files
- Step 5. Text recognition and quality control
- Step 6. Metadata and access rights
- Step 7. Uploading to AI search and testing with questions
- Copyable checklist template
- Common mistakes
- Source documents and verification method
Quick Overview
- Start with questions, not with the scanner. A list of 30–50 real employee questions determines which documents and which fields are needed.
- A scan does not automatically replace the original. Retention periods are set, in particular, by Rosarchive List No. 236: for example, primary accounting documents are kept for 5 years, employment contracts for 50 or 75 years.
- Resolution should be at least 300 dpi. Tesseract documentation indicates that the OCR engine works best with images at 300 dpi or higher.
- Check the recognized text using a sample. OCR errors later turn into AI answer errors.
- Set access rights before uploading to search, otherwise AI may show a document to someone who should not see it.
Who this checklist is for and what it does not cover
This checklist is for a company that has anywhere from several boxes to several hundred boxes of paper documents and needs to search them with AI: find contract terms, correspondence history, or act numbers. It is written for a project run by the company itself or by a contractor working on its behalf.
We do not cover scanner selection, industrial high-volume scanning, state and municipal archives, or electronic document management rules. OCR solution selection is described in detail in the article on document recognition, and the AI search architecture is covered in the article on a business RAG system.
Terms. *OCR* — optical character recognition, turning an image of a page into text. *Text layer* — recognized text inside a PDF that can be searched and copied. *dpi* — dots per inch, a measure of scan resolution. *Metadata* — document fields: type, date, number, counterparty. *RAG* — a setup in which a language model answers based on retrieved document excerpts. *EPC* — expert review commission of an archival institution.
What You Need Before You Start
| Role | Responsible for | Who usually performs it |
|---|---|---|
| Project owner | Goal, budget, final acceptance | Head of the department that will use the search |
| Archive owner | Inventory, retention periods, file checkout process | Records manager, archivist, office manager |
| Lawyer | Retention periods, personal data, fate of originals | In-house or outside counsel |
| IT and information security | Storage, access rights, model hosting location | IT department or contractor |
| Scanning operator | Paper preparation, scanning, file names | Employees or scanning contractor |
| Power users | Questions for testing, answer evaluation | 2–3 employees who search the archive most often |
Also prepare: a workspace for handling files, a scanner with an automatic document feeder for standard sheets and a flatbed mode for bound or fragile documents, and file storage with backup.
Each checklist item below is written as an action, a responsible person, and a “done” criterion. Check off an item only when the criterion has been met.
Step 1. The goal and the questions the search must answer
- ☐ State the task in one sentence. For example: “Lawyers find the terms of any supplier contract from 2019–2025 without going to the archive.” Who: project owner. Done: the sentence is agreed with future users.
- ☐ Gather 30–50 real questions. Take them from archive requests, emails, and chats. Who: power users. Done: a table with a document listed for each question showing where the answer is located.
- ☐ Define the answer type. Do you need a quote with a document number, a summary, or a table? Who: project owner. Done: the answer format is described for each question group.
- ☐ Record the current baseline. How long does it currently take to find one document? Measure it across several requests. Who: power users. Done: the measurement is recorded and can be compared after launch.
Step 2. Inventory and document selection
- ☐ Create an inventory of boxes and files. Who: the archive custodian. Done: each box has a number, date range, and document type.
- ☐ Mark what should be digitized. Scan what is needed to answer the questions from Step 1. Who: the project owner and the archive custodian. Done: each box is marked “digitize,” “store without digitizing,” or “consider for destruction.”
- ☐ Check retention periods. Reference point: the List of Standard Management Records Archival Documents, approved by Order No. 236 of the Russian Federal Archival Agency dated 12/20/2019. For example, contracts not listed in separate articles of the List — 5 years after the expiration date, with an EPC note (Item 11); primary accounting documents — 5 years, provided an audit has been conducted (Item 277); employment contracts — 50/75 years (Item 435): 75 years for files completed before January 1, 2003, and 50 years after that. Who: legal counsel and the archive custodian. Done: the retention period is listed in the inventory for each document type.
- ☐ Decide the fate of the originals. A scan for search does not mean the paper copy can be destroyed. Who: legal counsel. Done: a written decision on which originals are retained and where they are kept.
- ☐ Mark sensitive documents. Personnel files, medical certificates, documents containing passport data. Who: legal counsel and Information Security. Done: such files are marked in the inventory and a special access procedure has been defined for them.
Step 3. Preparing paper for scanning
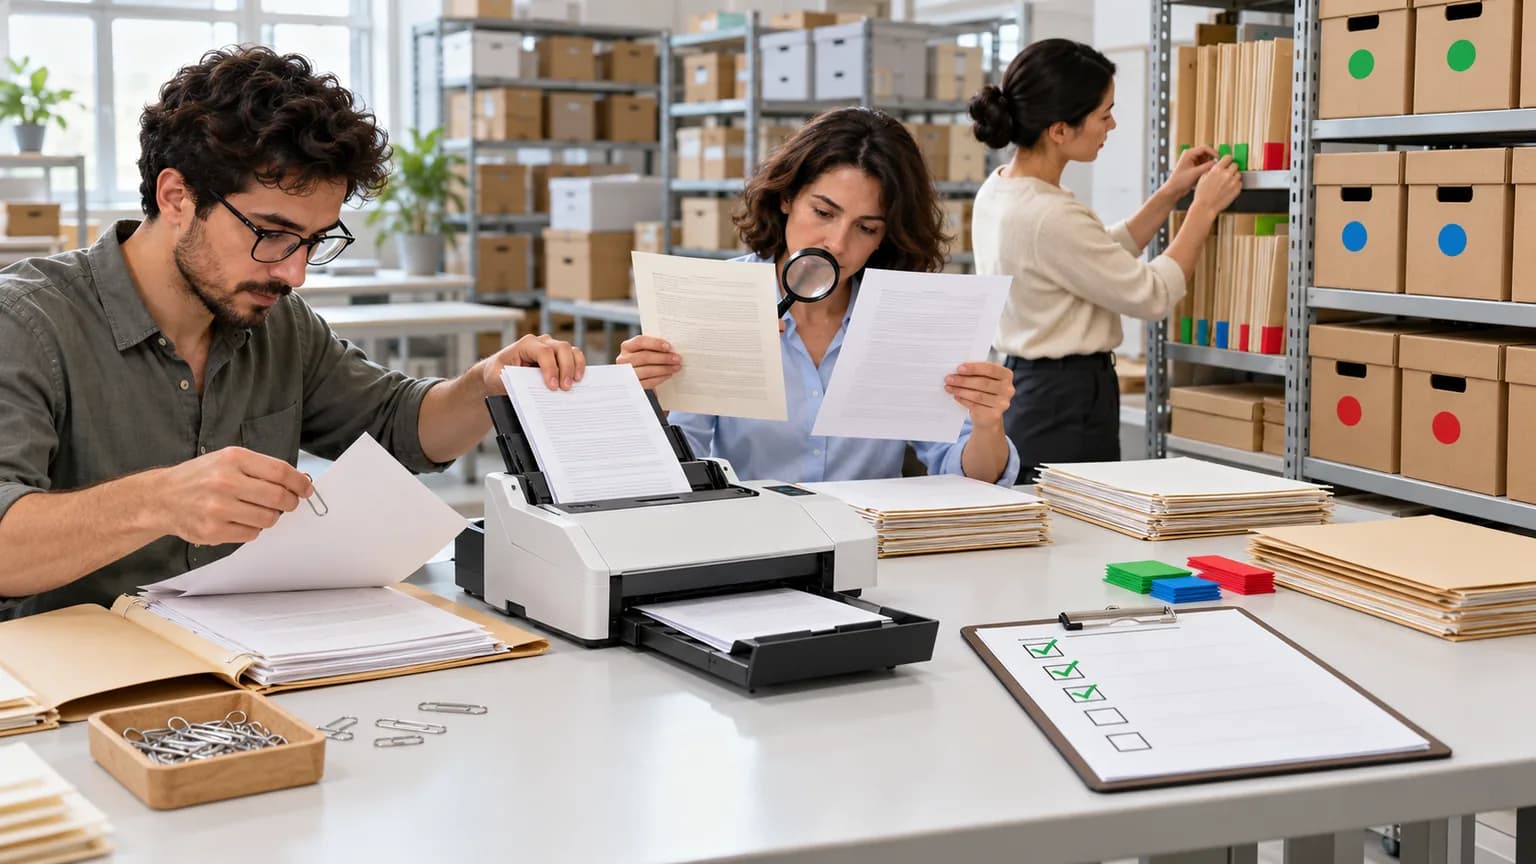
- ☐ Remove paper clips and staples, and unbind files where permitted. Do not unbind stitched and sealed files without approval from the archive custodian. Who: scanning operator. Done: sheets for the automatic document feeder are free of metal and adhesive joints.
- ☐ Separate fragile, wrinkled, and nonstandard sheets. These are scanned in flatbed mode. Who: scanning operator. Done: separate stack with a label.
- ☐ Keep the page order and document boundaries intact. Use divider sheets between documents. Who: scanning operator. Done: one document = one stack, and the order matches the file.
- ☐ Maintain a file checkout log. Who: the archive custodian. Done: for each file, it is recorded who took it, when, and when it was returned.
Step 4. Scanning settings and files
Tesseract documentation indicates that the engine works best with images at a resolution of at least 300 dpi. This is a good minimum threshold for other OCR systems as well, unless their documentation says otherwise.
| Situation | What to choose | Why |
|---|---|---|
| Standard printed text | 300 dpi, grayscale | Enough for OCR, and files are smaller than color scans |
| Blue signatures, color seals, and stamps | 300 dpi, color | In grayscale, the seal may blend into the text |
| Small font, tables, drawings | Above 300 dpi, test scan | Check recognition on a sample before launching the workflow |
| Long-term storage of copies | PDF/A | The ISO 19005 format was created for long-term preservation: PDF/A-1 was published in 2005 and is based on PDF 1.4 |
- ☐ Make a test scan of 20–30 typical pages. Recognize them using the selected OCR. Who: scanning operator and IT. Done: the settings are documented in the instructions.
- ☐ Set the file naming convention. For example: type_date_number_counterparty. Who: IT and the archive custodian. Done: the rule is documented, and file names are unique.
- ☐ One document — one file. A multi-page contract with attachments is stored as a single PDF, not as loose pages. Who: scanning operator. Done: a spot check of 10 files passed without errors.
- ☐ Keep the source images. If OCR needs to be rerun, there is no need to scan everything again. Who: IT. Done: the source files are stored in a repository with a backup copy.
Step 5. Text recognition and quality control
- ☐ Add a text layer to all PDFs. Who: IT or the vendor. Done: each file is searchable by keyword.
- ☐ Review a sample. Take random pages from each document type and compare the recognized text with the original: numbers, dates, amounts, full names. Who: subject matter experts. Done: critical fields are recognized without errors, or errors have been corrected.
- ☐ Check tables, handwritten notes, and stamps separately. OCR handles these worst of all. Who: subject matter experts. Done: a decision has been made for such documents — correct manually, enter the data in metadata, or mark as “image only.”
- ☐ Rotate and straighten pages. Who: scanning operator. Done: there are no upside-down or skewed pages in the sample.
Step 6. Metadata and access rights
- ☐ Approve the field set. Minimum: document type, date, number, counterparty or author, department, retention period, access level. Who: the project owner and the archive custodian. Done: the fields are defined with permitted values.
- ☐ Fill in the fields for each document. Some fields can be extracted automatically, but sample verification is mandatory. Who: executor or vendor. Done: there are no empty required fields in the sample.
- ☐ Assign access rights before uploading to search. AI search should show the document only to users who are authorized to see it. Who: IT and Information Security. Done: rights have been checked using test accounts for different roles.
- ☐ Decide where the model will run. Documents containing personal data and trade secrets cannot always be sent to an external service. We covered the rules in the article on customer data and AI. Who: legal and information security. Done: a written decision on where to host the model.
Stage 7. Upload to AI search and test with questions
- ☐ Upload files with metadata to the knowledge base. The quality of text extraction from PDF depends heavily on the parser — a comparison of tools is included in the article on PDF parsing for RAG. Who: IT or a contractor. Done: all files are indexed, and upload errors have been reviewed.
- ☐ Set up document chunking. A contract with attachments is split differently than a letter — see the article on document chunking. Who: IT or a contractor. Done: each chunk includes the document number and date.
- ☐ Run the questions from Stage 1. For each one, check whether the right document was found, whether the answer is correct, and whether there is a source citation. Who: business users. Done: the results are in a table, and the errors are reviewed by cause — scan, OCR, metadata, or search.
- ☐ Compare against the Stage 1 baseline. Who: project owner. Done: a decision on whether to roll out to the next boxes or make improvements.
Copyable checklist template
Copy the template into a spreadsheet or task tracker and enter your own owners.
STAGE 1. GOAL AND QUESTIONS
☐ The task is stated in one sentence — project owner — aligned with users
☐ 30–50 real questions have been collected with the source document identified — experts
☐ The answer format has been defined — project owner
☐ The current search time baseline has been recorded — experts

STAGE 2. INVENTORY AND SELECTION
☐ Inventory of boxes and files — archive owner
☐ Statuses: digitize / retain / consider for destruction — owner + archive
☐ Retention periods under Rosarkhiv List No. 236 entered in the inventory — legal + archive
☐ Written decision to retain originals — legal
☐ Sensitive files are marked — legal + information security

STAGE 3. PAPER PREPARATION
☐ Paper clips and staples removed, files unbound where permitted — executor
☐ Fragile and nonstandard pages set aside for flatbed scanning — executor
☐ Separator sheets placed between documents — executor
☐ File issuance log is maintained — archive

STAGE 4. SCANNING AND FILES
☐ Test scan of 20–30 pages, settings recorded (not below 300 dpi) — executor + IT
☐ File naming convention approved — IT + archive
☐ One document — one file — executor
☐ Source images preserved with a backup copy — IT

STAGE 5. OCR AND QUALITY CONTROL
☐ Text layer in all PDFs — IT
☐ Spot-check of numbers, dates, amounts, full names — experts
☐ Decision on tables, handwriting, stamps — experts
☐ Pages rotated and aligned — executor

STAGE 6. METADATA AND ACCESS
☐ Field set approved — owner + archive
☐ Required fields completed and spot-checked — executor
☐ Access rights verified using test roles — IT + information security
☐ Decision on model hosting — legal + information security

STAGE 7. AI SEARCH AND ACCEPTANCE
☐ Files indexed, upload errors reviewed — IT
☐ Chunking configured by document type — IT
☐ Stage 1 questions run, errors reviewed by cause — experts
☐ Result compared with the baseline, decision made on expansion — owner
Common mistakes
- Scan everything indiscriminately. Without the questions from Stage 1, the budget goes to documents that nobody is looking for.
- Destroy the originals after scanning. Retention periods and requirements for document form are determined by more than whether a scan exists; that is a legal decision.
- Choose low resolution to save space. OCR errors in numbers and amounts cannot be fixed later without rescanning.
- Merge several documents into one file, or split one document into multiple files. AI search will mix up sources and dates.
- Skip metadata. Without the date, number, and counterparty, AI cannot tell an active contract from a terminated one.
- Give everyone access to everything. AI search will faithfully show a personnel file to an employee who did not have access to the paper archive.
- Approve the project based on impressions. Without questions, a baseline, and error analysis, you cannot tell whether search actually improved.
Source documents and verification method
We verified the factual claims on October 25, 2026:
- Rosarkhiv Order No. 236 dated 12/20/2019 "On Approval of the List of Standard Administrative Archival Documents…" (registered with the Ministry of Justice on 02/06/2020, No. 57449) — items 11, 277, 435, and the note on the 50/75-year retention period;
- Tesseract documentation Improving the quality of the output — recommendation for a resolution of at least 300 dpi;
- Library of Congress, PDF/A-1 format description — ISO 19005-1:2005 standard based on PDF 1.4.
The stage structure, roles, “done” criteria, and sample sizes (30–50 questions, 20–30 test-scan pages) are our editorial methodology for the pilot, not a regulatory requirement. Retention periods for specific documents in your organization may also be determined by other acts — confirm them with legal counsel.
How AIrassvet helps connect a paper archive to AI search
Digitization pays off when a scan becomes a document that allows AI to find an exact answer with a source citation. On the AIrassvet website the company lists RAG systems and corporate knowledge bases, computer vision solutions for working with documents, as well as process audits, data preparation, integration, and testing. For this task, that means:
- auditing employee and archive questions: which documents and fields are actually needed for search;
- configuring OCR and metadata extraction from scans with spot-checked quality control;
- a RAG knowledge base with access rights and testing against control questions before launch.
The first step is to choose one process where employees search for paper documents and record the current result, data sources, constraints, and acceptance criterion.
Bottom line: questions and retention periods first, then the scanner
A paper archive becomes useful for AI search once all seven stages are completed: goal and questions, selection based on retention periods, paper preparation, scanning at no less than 300 dpi, OCR review, metadata with access rights, and acceptance against real questions.
Start with one document group — for example, supplier contracts for several years. Follow the template, compare search time before and after, and only then expand digitization to the rest of the archive.