Assessing the complexity of tasks and projects starts by separating five things: functional size, implementation complexity, effort, calendar duration, and uncertainty. One metric does not replace the others. To make an informed decision, it helps to compare requirements, UI behavior, properties of the existing code, and the team’s capabilities, and then build a delivery forecast.
COSMIC helps measure functional size, while IFPUG SNAP adds nonfunctional requirements to the picture. Cognitive Complexity and Cyclomatic Complexity show different properties of code. A state model reveals scenarios and transitions, an screen matrix helps compare implementations, Story Points support team planning, and Nielsen heuristics identify usability issues. They can be used together as long as you do not add incomparable units into a single “objective score.”
This is a detailed guide for developers, analysts, team leads, project managers, and clients. The main examples relate to frontend work: forms, user accounts, editors, data import, and integrations. The principles apply more broadly, but industry-specific standards and estimate-based pricing are not covered here.
This material was prepared for the website of Vladimir Lomtev’s AI studio. The methodology descriptions were checked against primary sources on October 29, 2026. The proposed matrices and the end-to-end example are instructional tools in this article. They are not the result of a study, a real client case, or a formally completed COSMIC/SNAP measurement.
Contents
- What exactly is being assessed
- Comparison of eight methods
- COSMIC
- IFPUG SNAP
- Cognitive Complexity
- Cyclomatic Complexity
- States and statecharts
- Screen and component matrix
- Story Points and Planning Poker
- Nielsen heuristics
- End-to-end project example
- Timeline forecast
- Assessment template
- Frequently asked questions
What exactly is meant by complexity
In development discussions, a “complex task” can mean very different situations. There are many requirements. There are few requirements, but an algorithm has to be invented. The algorithm is known, but the code is tangled. The code is simple, but access to an external system will only be available after approval. From a management perspective, these are different problems.
Until participants agree on what the estimate means, the same number creates false consensus. The developer means technical difficulty, the manager means delivery date, and the client means price. The mistake shows up later, when it turns out that testing, integration, or data preparation were not included in the promise.
Size, complexity, effort, timeline, and risk
Size describes the volume of defined requirements in the chosen measurement system. Implementation complexity — the characteristics that make a solution difficult to design, code, test, or maintain. Effort — the amount of human work. Timeline — the calendar time to the agreed result. Uncertainty — the lack of knowledge about requirements, the solution, and delivery conditions.
Risk is tied to possible events and their consequences. For example, an unknown API contract is uncertainty, while the chance that a change to it will require reworking a form can be treated as a separate risk. Do not hide all of this inside one arbitrary coefficient.
| Characteristic | Working question | Possible result |
|---|---|---|
| Functional size | What functions should the system perform? | Size under the selected method and its rules |
| Nonfunctional requirements | What additional qualities of the result are mandatory? | Agreed requirements and applicable measurements |
| Solution complexity | What is hard to implement, and why? | A list of technical factors and architectural decisions |
| Effort | How much work is needed for the finished result? | A range of effort with an agreed scope |
| Timeline | When can the result be delivered? | A forecast with dependencies and conditions |
| Uncertainty | What do we not know yet? | Questions, checks, and a clarification plan |
| Risk | What could change the forecast? | An event, its consequences, and the team’s action |
Simple example: changing the text on a button is usually low effort to implement. But if the text is part of a legally approved notice, the calendar timeline may depend on outside approval. Increasing the “code complexity” because of that makes no sense. The expectation should be shown as a separate dependency.
Why bigger is not always harder
A hundred similar cards assembled from a ready-made template may require more content than engineering invention. A single visual editor with undo and shared access may look compact, yet contain complex behavior.
That is why the number of screens is useful for inventorying scope, but not enough for estimating a project. You need to understand the uniqueness of templates, states, data, interactions, and quality requirements. In practice, the first outcome of estimation is often a refined scope description, not an hour count.
Comparison of complexity estimation methods
The table expands the original list of methodologies and shows which management task each approach solves. The methods were selected per the user’s request; this is a comparison by purpose and limitations, not a ranking of accuracy. The article does not claim a universal experiment proving that one approach is superior for all projects.
| Method | What it measures or describes | Use in frontend work | What it does not provide on its own |
|---|---|---|---|
| COSMIC | Functional size | Functional processes and data movements within a defined boundary | Ready-made hours, price, animation complexity |
| IFPUG SNAP | Nonfunctional size within the method’s rules | Applicable requirements for the UI and other implementation qualities | A universal accounting of all project costs |
| Cognitive Complexity | Structural difficulty in understanding control flow | Complex handlers, conditions, nested branching | A full assessment of architecture and future development |
| Cyclomatic Complexity | Linearly independent paths in the control-flow graph | Branching in checks and logic | The total number of tests and the cost of the task |
| State model / statecharts | States, events, and transitions | Forms, import, saving, conflicts, undo | An automatic time norm per state |
| Screen and component matrix | Relative implementation profile based on team rules | Matching screens and reuse | Standardized cross-team size |
| Story Points / Planning Poker | The team’s relative work estimate | Discussion of scope, complexity, and uncertainty | A common currency for comparing teams |
| Nielsen heuristics | Potential usability issues | Errors, feedback, control, and clarity | The effort required to fix a found issue |
The definitions rely on COSMIC, IFPUG SNAP, SonarSource, Stately, Scrum Alliance and Nielsen Norman Group.
It is more useful to choose the method based on the question. For purchasing development, you may need a comparable requirements size and an internal cost model. For refactoring, code analysis. For a form with unclear behavior, states. For sprint planning, team decomposition and estimation of discussion-ready tasks.
COSMIC: functional size instead of counting screens
COSMIC measures functional user requirements through data movements. The model distinguishes Entry, Exit, Read, and Write; one counted movement has a size of one COSMIC Function Point, or CFP. Before measurement, you define the purpose, scope, boundary, and functional users. Details are laid out in the official COSMIC process description.
For frontend work, the measurement boundary matters. Interaction with a separate backend may cross the boundary as exchange with another software functional user. You cannot automatically treat any API request as a read from persistent storage inside the frontend. The Read/Write rules and boundaries are described in the Measurement Manual v5.0.
What to prepare before measurement
In a working review, it is first useful to describe the user outcome: find a record, change data, get confirmation. Then determine what data is needed, where it comes from, and who interacts with the measured part of the system. After that, the specialist applies the method’s rules.
For a profile edit form, this means clarifying the data set, the triggering event, and the expected result of the operation. A screen image without a behavior description is not enough. Errors, confirmations, and service exchanges require a thoughtful analysis of the requirements.
There is intentionally no “formal CFP calculation by buttons” here. The training list of actions helps prepare material for measurement, but it is not yet a measurement. For the result to be called a COSMIC size, the definitions, uniqueness rules, and aggregation rules must be followed.
Where COSMIC is useful in a project
Functional size helps discuss the product scope separately from the chosen framework. For example, a team may rework the implementation while keeping the functional requirements unchanged. In that case, comparison should not rely only on the number of new lines of code.
Practical use in budget estimation requires an historical link between measured size and effort in a comparable context. The CFP value alone does not tell you how mature the design system is, how many integrations are unstable, or how long acceptance will take.
For an interface with complex visuals, it is worth additionally describing the visual and behavioral requirements. If their impact is not represented in the chosen model, a small functional size should not be treated as a promise of fast development.
When not to start with formal size
For a small team and a one-off fix, the cost of detailed measurement may be higher than the value of the decision. In that case, it is enough to write down the scenario, acceptance criteria, and constraints clearly. A formal method makes sense where repeatability and comparability are needed.
At an early stage, the requirements may be insufficiently defined. Then the result should reflect the approximation and the estimation method used. A high-level count from a presentation cannot be passed off as a full measurement of detailed requirements.
IFPUG SNAP: non-functional requirements size
SNAP stands for Software Non-Functional Assessment Process. IFPUG describes it as a complement to functional sizing: an assessment of non-functional requirements using its own categories and rules. The official overview lists four categories and fourteen subcategories. IFPUG’s SNAP description.
For frontend work, the method is relevant in particular because of the User Interfaces subcategory and aspects of data handling in dialogs. This is covered in a separate IFPUG resource on measuring interfaces. However, the mere presence of an interface requirement does not determine its size: applicability and counting are defined by the method guide.
How to prepare requirements for discussion
The phrase “make it high quality” does not help estimation. It is better to write down observable conditions: supported devices, input options, presentation requirements, accessibility, and environment constraints. Then determine which of them are covered by the chosen method and which are handled separately.
For example, the client wants to use a table with a keyboard and preserve context after an error. A single label of “non-functional requirements” is not enough: you need to describe the behavior, the verification criterion, and the implementation boundaries. Not all such requirements necessarily become SNAP points in the same way.
For accessibility, a separate verifiable basis is useful. W3C WCAG Quick Reference helps find requirements for focus, keyboard access, and other interface characteristics. It is a source of criteria, not a time sheet and not an automatic SNAP calculator.
Why SNAP should not be turned into a surcharge for complex design
The arbitrary rule “a pretty screen equals plus ten SNAP points” is not part of the method. The visual richness of the design and formal requirement categories are different things. Complex animation may require a separate technical specification and prototype validation.
It is also wrong to assume that SNAP covers any expectation, coordination, or organizational risk. These affect the project, but do not necessarily belong to the measurable size of the software requirements. Such items should remain in the dependency register and delivery forecast.
How to use it together with functional estimation
Keep the results separate: functional size, non-functional size, additional constraints, and an effort model. Numbers from different methods cannot be added together without your own justified conversion model. The sum of CFP and SNAP points does not become a new standard unit.
A useful output for the team is a linked requirements register. Each requirement has a source, an acceptance criterion, and a place in the estimate. This helps avoid losing work and double-counting the same item.
Cognitive Complexity: how hard code is to understand
Cognitive Complexity is a SonarSource metric that approximates the structural difficulty of understanding control flow. Its rules account for disruptions to linear reading and for nesting; certain convenient constructs are handled by special rules. It is not a psychological test of the developer and not a measure of every aspect of architecture. Cognitive Complexity white paper.
In frontend work, a useful analysis target is a handler that checks permissions, validates data, chooses how to save, and manages message display at the same time. The metric helps identify such spots for review. But the final refactoring decision requires reading the code and understanding the scenario.
Example of a nesting problem
Let’s look at a simple example:
function canSave(user, draft, connection) {
  if (user) {
    if (user.canEdit) {
      if (draft.isValid) {
        if (connection.isOnline) {
          return true;
        }
      }
    }
  }
  return false;
}
For a simple rule, this kind of nesting can be replaced with sequential checks or a more expressive predicate. But in a real system, the function may also be responsible for the reasons a save is blocked. Reducing it to a short logical expression can hide important differences between “no permissions” and “no connection.”
So the goal is to make the behavior model clear. If the interface needs to show different messages, describe the refusal reasons and their priority separately. Lowering the metric without preserving that meaning does not improve the product.
The article does not give an exact Cognitive Complexity score for this code: it was not checked with a specific analyzer. To get a reproducible value, you need to fix the tool, version, and language rules.
What the metric shows in an existing project
When improving a complex module, it helps to look at the distribution of issues: one heavy handler, several nested conditions, or dependencies spread across components. The number itself does not say which requirements will be affected by a change.
For example, the task “add one more status” may be small in a well-designed module and expensive in code with duplicated checks across the app. In the estimate, it is worth recording the reason: the change requires coordinating several places and guarding against regressions. That wording is more useful than an unexplained “technical debt” markup.
What you cannot infer from Cognitive Complexity
A low function score does not prove that the whole component is easy to maintain. Complexity may live in effects, asynchronous links, implicit conventions, and state distribution. These are separate analysis topics.
You also should not predict the cost of a new system from a desired average score. The code has not been written yet, the structure has not been chosen, and there is no normative “score-to-hours” mapping. For planning, it is more useful to examine risky areas and rely on your team’s observations.
Cyclomatic Complexity: branching and independent paths
Cyclomatic Complexity is the cyclomatic complexity, which is related to the number of linearly independent paths in a control-flow graph. The classic formula is V(G) = E − N + 2P, where E is edges, N is nodes, and P is components. At the function level, analyzers use branching-count rules. SonarSource explanation.
In practical analysis, it is important to know the language rules: logical operators, switch variants, switch, exception handling, and other constructs may be counted differently. SonarSource publishes metric definitions and language details in the SonarQube documentation.
Example for frontend validation
Imagine a function with three sequential independent checks:
function getError(form) {
  if (!form.name) return 'name_required';
  if (!form.email) return 'email_required';
  if (!form.acceptedTerms) return 'terms_required';
  return null;
}
In a simplified count, “base one plus three branches” gives four. This is an instructional calculation for the structure shown. It is not a tool report and does not automatically apply to the whole form.
The interface may additionally have server-side validation, retry, button disabling, and accessible error announcements. Those requirements do not disappear because the function has a small score. And conversely, a branchy but clear rules reference does not necessarily need rewriting.
Why the number of paths is not the same as the number of all tests
Independent paths are a property of the control graph. A complete test set also depends on data values, boundaries, condition combinations, asynchronous events, and requirements. Some paths may be unreachable under real-world constraints.
So the statement “complexity is four, so exactly four tests are needed” is too strong. For a specific coverage criterion, you can build a matching set, but you cannot derive the adequacy of the entire product test effort from one metric.
For a form with amounts and currencies, you need to test meaningful constraints, not just branches. An empty string, rounding, and number formatting may fall into the same branch but create different defects.
How to combine two code metrics
Cyclomatic Complexity helps reveal branching, while Cognitive Complexity shows the structure that makes understanding harder. The gap between them is useful for discussion. A flat list of options and a deeply nested algorithm may require different actions even with similar size.
In the report, name the problematic function, the scenario it affects, and the expected impact on work. Then decide whether a separate refactor, a local change, or further investigation is needed. The metric becomes a basis for a question, not an automatic verdict.
State models and statecharts: behavior complexity
A state model describes which modes the system is in and which events trigger transitions. Statecharts extend the approach with features such as hierarchy and parallel regions. It is a way to express behavior, not a ready-made effort scale. Stately introduction.
For frontend work, this kind of analysis is especially useful when one UI mockup is not enough. A single import screen can be empty, load a file, show validation, wait for error resolution, and report completion. Visually it is one screen, but the work is not limited to one state.
Behavior first, then quantity
Start by asking what the user can do in each mode. Can the upload be canceled? Is it allowed to change the file after validation? What happens if the connection is lost? Will the selection persist after a page refresh?
Questions like these uncover requirements before components are written. They are useful even without a specialized library: the model can be maintained as a transition table and discussed with the analyst, designer, and tester.
Example training table:
| State | Event | Condition | Result |
|---|---|---|---|
| No file selected | File selection | Format is valid | Start upload |
| Uploading | Cancel | The operation can be interrupted | End the local attempt, restore selection |
| Validation | Result received | No errors | Open preview |
| Validation | Result received | There are fixable errors | Show the list and available actions |
| Preview | Confirmation | Permissions and data are current | Start import |
| Importing | Connection lost | Final result is unknown | Check status, avoid blind duplication |
The last line is especially important. Loss of connection does not prove that the server did nothing. The requirements should define status recovery, not just add a red notification.
Why a set of boolean variables hides complexity
Four independent flags theoretically allow 2⁴ = 16 combinations. Not all combinations are necessarily reachable or meaningful. If the app should not be simultaneously “saving” and “successfully saved,” the data model should help eliminate that contradiction.
This matches the general advice from React on state structure: avoid contradictory and redundant state. But the combination formula is only an arithmetic upper bound, not the number of real screens or required tests.
For estimation, it is more important to identify valid combinations and transitions. Parallel loading of a reference list and text editing differ from a single sequential flow. A hierarchy can make the description more compact, but it does not replace verification of actual behavior.
What to record as complexity
A useful profile includes the number of meaningful modes, conditional transitions, asynchrony, cancellation, retry, recovery, conflict, and parallel actions. Record unknown rules separately. This helps reveal work that does not appear in a static mockup.
Do not assign a universal price to a transition. A simple tooltip opening and restoring an import after a failure may have the same arrow shape but different implementation. The model provides structure for decomposition and testing.
Complexity matrix for screens and components
A matrix is a practical team tool for comparing implementation across common characteristics. It becomes useful when the criteria are defined, the examples are aligned, and the estimates are tied to follow-up observations. There is no single required industry-wide scale for any screen matrix.
Below is a teaching author-created matrix. It is not related to COSMIC, SNAP, or Scrum and has not been empirically calibrated. It can be adapted to start a team discussion while keeping separate factors and unknowns.
Which factors to include
| Factor | Low level | Medium level | High level |
|---|---|---|---|
| Uniqueness of the presentation | Ready-made template without changes | Adaptation of several components | New visual interaction model |
| Behavior | Simple sequential scenario | Several alternatives and errors | Parallelism, conflicts, recovery |
| Working with data | One aligned source | Matching multiple datasets | Large volume, complex transformations, consistency |
| Integrations | Verified contract | Changing contract with an available owner | Unknown behavior or multiple dependent systems |
| Reuse | The component already fits | Requires extension | No suitable foundation exists |
| Environments and quality | Agreed baseline set | Additional devices and conditions | Complex constraints and checks |
| Uncertainty | Rules and examples are known | There are questions that can be clarified | The solution principle or acceptance criteria are unknown |
The matrix should not reward complexity. It helps explain why a task requires attention and how to reduce risk. If the API is unknown, a useful action may be to verify the contract, not to inflate the number in every column.
Is a single overall score needed
To start, a profile is enough. A screen can be visually simple and complex in integrations. One final number hides that difference, while the team's decision depends on it.
If an internal index is required, you can agree on an ordinal scale, for example 0–3 for observable levels. But the difference between levels does not become equal to the difference in hours. The value “unknown” should be stored separately, not replaced with zero or the maximum score.
Weights and thresholds are team hypotheses. They are checked against completed work. You cannot declare a total of “twenty points” equivalent to “ten days” without data and a description of applicability.
How to avoid double counting
Behavior, validation, and the number of errors can describe the same work. If you add an independent surcharge for each one, the estimate will bloat. Separate factors are useful for discussion, but the effort model must explain how they are connected.
It is equally important not to count a shared component again on every screen. The creation or enhancement of the common foundation, integration on a specific page, and context-specific testing are estimated separately. Reuse reduces part of the work, but it does not automatically reduce it to zero.
How to calibrate the matrix
After the task is completed, compare the initial profile with the actual result. What turned out to be the main driver: design, data, contract, regression, or an unaccounted-for state? Was the requirement known at the time of estimation? These are different reasons for variance.
If the new factors do not help explain decisions, the matrix should be simplified. The usefulness of the tool is determined by the quality of the discussion and the follow-up check, not by the number of columns.
Story Points and Planning Poker: team-based relative estimation
Story Points are used for relative estimation within a team. They help discuss scope, complexity, and uncertainty by comparing work to known tasks. They are not standardized person-hours. Scrum Alliance separately warns against converting them at a fixed rate and comparing teams by velocity. Scrum Alliance material.
Planning Poker is a way to facilitate discussion: participants independently choose an estimate, reveal their choices at the same time, and discuss the differences. After clarification, the item can be estimated again. The procedure is described by Mountain Goat Software.
What estimate differences tell you
If one participant sees a small tweak and another sees a large amount of work, it is useful to uncover the assumptions. The first may have assumed a ready-made component. The second may remember an old saving mechanism. The third may be factoring in the mobile version and regression testing.
Such differences do not need to be averaged immediately. They show different models of the task. After discussion, it may turn out that two estimation variants are needed: extending the existing solution and building a new foundation.
The team may also discover that the task is not yet suitable for a meaningful estimate. In that case, the sensible outcome is a specific question or investigation. A large number should not mask a lack of understanding.
How to choose reference tasks
Take completed tasks with a clear scope of deliverables. It is important to remember not only coding, but also testing, fixes, and required integration. Compare the new item with several such examples.
The reference task should be recognizable to the team. If one person completed it under unknown conditions a year ago, shared memory may be unreliable. It is helpful to keep a short description, definition of done, and important constraints.
When the team composition or technology changes, old benchmarks need to be revisited. Keeping the old numbers just for a nice chart does not ensure comparability.
Why points should not be used as a KPI
Different teams may use different scales and rules for what work is included. Growth in the total number of points does not prove growth in useful output. If the number becomes the goal, participants are incentivized to change the estimating process instead of the delivery process.
For discussing the outcome, it’s better to look separately at completed product goals, quality, and the actual delivery. Relative estimation remains an internal planning tool. It does not tell you which developer is "twice as effective."
Story Points Are Not Required for Scrum
Scrum is not just about points and poker. The Scrum Guide describes working with the Product Backlog, refining and estimating its items, but it does not prescribe a specific scale. This is addressed directly by Scrum.org in its article about the myth of mandatory Story Points, and the original rules are available in the Scrum Guide.
If the tasks are small enough and comparable, the team can forecast based on completed items. If the items vary greatly, you’ll need to start with decomposition first. The choice of tool depends on the context, not on a requirement to fill in the points field at all costs.
Nielsen Heuristic Evaluation: Usability Problems
Heuristic evaluation checks an interface for potential usability issues. Nielsen’s principles include system status visibility, match between the system and the real world, user control, consistency, error prevention, recognition rather than recall, efficiency, minimalist design, help users recover from errors, and help/documentation. These are guidelines for expert review. Nielsen's Ten Heuristics.
The method can be applied to a prototype or a finished product. It helps identify likely problems, but it does not replace research with real users. NN/g describes preparation, independent review, and consolidating findings in the evaluation guide.
How a UX Problem Becomes a Development Task
Imagine an import flow where nothing changes after the button is clicked. The expert notes the lack of feedback. Then the team clarifies the solution: show loading progress, server-side processing status, the ability to cancel, or just a message that the request was accepted.
These are different amounts of work. The wording "fix status visibility" does not define the effort until the behavior is chosen and the server contract is understood. The heuristic identified the problem; implementation estimation starts with the next step.
Another example is a confusing form error. Sometimes rewriting the message is enough. Sometimes you also need to preserve entered data, return focus to the field, and change the server response. The same user complaint does not mean the same engineering task.
Problem Severity and Fix Cost
Keep them separate. A very painful defect may require only a small fix. A barely noticeable issue may require major rework. The priority of the solution depends on the impact on the user and the product, while the work estimate depends on the chosen change.
A useful log includes the scenario, observation, expected impact, evidence, and possible solutions. If the impact is still only an expert hypothesis, say so. This helps decide where you need user testing and where a clear agreed-upon fix is enough.
Where Heuristics Are Useful in Project Estimation
Reviewing before development helps refine acceptance criteria. Instead of "the form is done when it submits data," you get a clear result with errors, recovery, and accessible feedback. That’s how you uncover work that would otherwise be added after the demo.
This is not a reason to expand the project without limits. Every new finding should go through scope review: is it required now, does it belong in the original criteria, or does it require a separate change? The estimate remains tied to the agreed outcome.
How to Estimate Front End Work Before Code Exists
Metrics for finished code are useful when modifying an existing application. For a new interface, requirements, mockups, user flows, and constraints come first. You do not need to invent future cyclomatic complexity for every component.
Break the interface down into several views: the user journey, the catalog of screens and templates, data and integrations, states, and quality criteria. Different views expose different gaps. Contradictions between them are useful findings in an evaluation.
What to Ask the Designer and Analyst
Clarify empty and error states, long text, data limitations, roles, and behavior on a small screen. Define what happens after a page refresh, going back, and clicking again. For complex scenarios, describe canceling and recovery.
A mockup of the happy path is only part of the contract. If it doesn’t show an error, that does not mean the error does not need to be implemented. But the developer also should not silently invent behavior and then present it as an inevitable expansion of scope.
Visual Complexity Requires Its Own Analysis
Animation, custom typography, complex grids, scaling, and rendering can increase the work even without many business features. For these tasks, a technical prototype is useful with a preselected question: does it test smoothness, compatibility, input method, or rendering accuracy.
The result of the prototype should reduce a specific unknown. "Try the library" is too broad. "Check whether it supports the required object highlighting on target devices" already helps shape the future solution.
Do not carry a strong demo example from the library over to the entire project. Real data, styling, accessibility, integration, and verification will be needed. Reuse is a premise that still has to be confirmed.
End-to-End Example: Estimating a Catalog Import
Imagine a fictional project: a user uploads a product catalog, maps columns, reviews errors, and confirms the import. The project and estimates below are created to explain the method. This is not a client case, a performance benchmark, or a formal function point count.
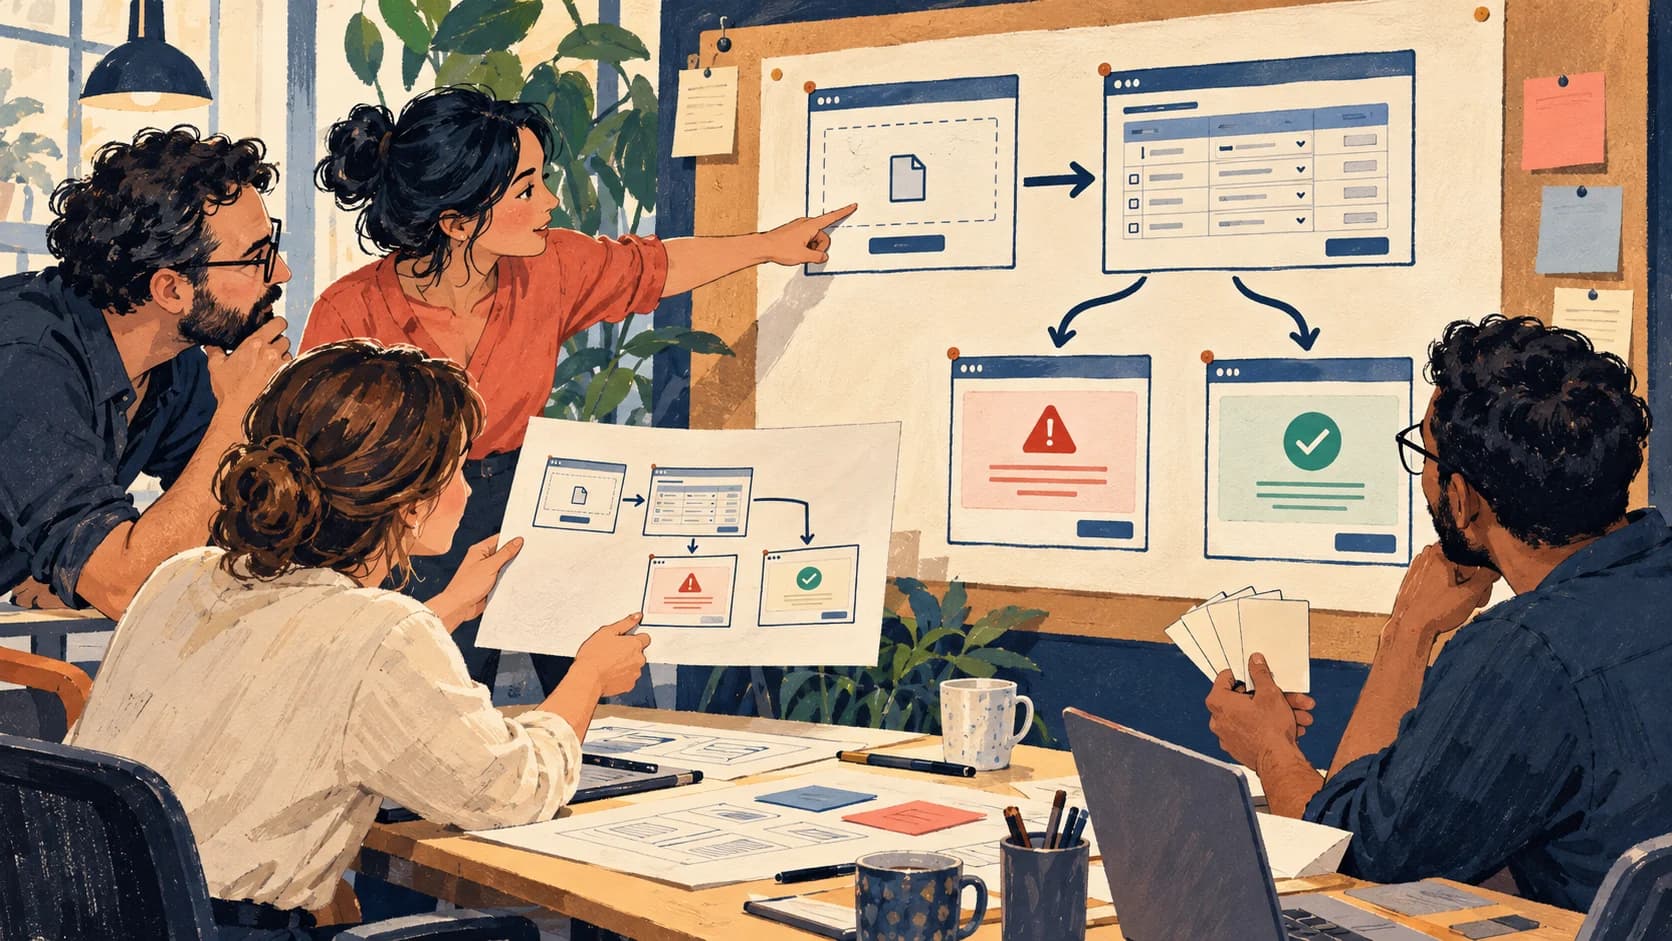
In a working session, the team maps the import-step prototype to the state diagram and estimation cards. This connects a static screen to behavior, integrations, and definition-of-done criteria. Each method answers its own part of the question.
First, define the scope of the outcome
The first version includes uploading an agreed format, field mapping, preview, error messages, and receiving the final status. Support for arbitrary sources, complex duplicate merging, and collaborative editing are not promised. These are the chosen conditions of the training example, not a universal import specification.
You need to clarify file constraints, behavior in case of partial errors, and how to recover after a connection drop. Until those are defined, the estimate remains provisional. Writing down the question is more useful than quietly assuming the server will "figure it out somehow."
Then review each approach
| Approach | What the team learns in the training import | Result for estimation |
|---|---|---|
| COSMIC | Where the boundary of the measured software is, and which functional processes and data are defined | A basis for formal measurement if needed |
| SNAP | Which applicable non-functional requirements for dialogs and the environment have been agreed | A basis for measurement under SNAP rules, without homemade points |
| Statecharts | Upload, validation, correction, confirmation, execution, recovery | A table of states, events, and transitions |
| Matrix | The novelty of column mapping, data complexity, and integrations | A relative implementation profile |
| Story Points | How prepared tasks relate to the team’s reference tasks | Team estimate after refinement |
| Nielsen | Does the user understand the status and the path to resolution | Feedback and recovery requirements |
| Code metrics | How the existing upload module is structured, if it is being changed | Scope of analysis and possible refactoring |
This table does not add up to a total. It shows which artifacts are needed to solve the problem. If functional size is not required, the team may skip formal measurement while still preserving a useful requirements analysis.
Decomposition by deliverables
It is useful to break out the base upload with status display, field mapping, error presentation, and operation confirmation. Each part should have a verifiable result. Splitting it only into “build the component,” “write the CSS,” and “then test it” is a worse way to show user journey readiness.
At the same time, shared dependencies are accounted for explicitly. The task contract, status-check mechanism, and cancellation handling may be used by several parts. They should not be counted in full inside each task without noticing.
Risky integration should be checked earlier if it determines the architecture. That does not necessarily mean implementing the entire backend before the UI. You need enough basis for the next decision.
What an additional requirement changes
Suppose that after the initial analysis, support was added for resuming an incomplete import on another device. Visually, a new screen may not be needed. But state storage, task identification, access rights, and status recovery all change.
This is a good example of complexity changing without an increase in the number of mockups. The original estimate was not automatically wrong if that requirement did not exist. The change needs to be logged and the affected parts reviewed.
If resuming was clearly documented from the start but the team missed it, that is a reason to improve the estimation process. For training, it is important to distinguish scope change from analysis error.
How to move from complexity to effort and timelines
Complexity helps explain the work, but forecasting requires additional data. You need the deliverable composition, the available team, comparable completed tasks, dependencies, and acceptance conditions. Without that, an “accurate estimate” is often just a detailed number.
For functional size, a model based on observed productivity is possible. COSMIC examines the relationship between size and effort through productivity in the official introduction to the method. But you cannot apply someone else’s coefficient without checking the context: the comparability of measurement and working conditions matters.
Forecast based on analogs
Choose completed tasks with similar outcomes and conditions. Compare not only the type of screen, but also new components, integrations, requirements quality, testing, and dependencies. If the analog differed, explain the expected impact.
It is useful to keep several examples, not a single “ideal case.” One successful fast release may not reflect the usual process. You also need to separate active work time from waiting time, if your tracking system allows it.
You do not need to create a huge database just for the first estimate. Start with a small agreed-upon history and a list of differences. If you do not have suitable data, say so: the forecast is expert-based, the basis is limited, and validation is planned after the first result.
Person-hours are not the same as calendar hours
Consider a simple arithmetic example. Task A takes 12 hours, and after that B can be done in parallel in 8 hours and C in 6 hours. The total amount of work is 26 person-hours. Under ideal conditions and with different performers available, the chain duration is 20 working hours: 12 + max(8, 6).
This is a training calculation. It does not include context switching, communication, waiting, or working-hour constraints. If one person does all the parts, the parallelism assumption does not hold. Dividing the total by the number of employees does not automatically produce the correct timeline.
For a project, draw the dependencies and note the availability of performers. Tasks that require one specialist or one test environment may compete for the same resource. That effect is not visible in the total complexity score.
What to include in effort
Define the readiness boundary: analysis, implementation, review, testing, fixes, integration, and release may be included in one estimate or tracked separately. The key is to make the rule explicit. Otherwise, teams compare different scopes under the same label.
Recurring cross-project work is better shown as separate items: environment setup, build, monitoring, migration, data preparation, acceptance. If you hide them inside each task, it is easy to both miss them and count them twice.
Not everything should be estimated at the same level of detail. For an early decision, a rough range and the main constraints are enough. For an imminent release, a more specific description is needed.
Range and conditions instead of false precision
A range is useful if it is clear what defines its boundaries. The lower bound may assume a ready-made contract and reuse, while the upper bound may assume limited enhancement of an agreed component. An unknown architecture may fall outside that range and require separate investigation.
Do not call an expert interval a statistical confidence interval without a model and data. Nor can you assign it a probability just because the numbers look reasonable. In communication, you need to distinguish expert judgment from an empirical forecast.
When suitable flow data is available, probabilistic forecasting is used. Scrum.org covers Monte Carlo forecasting. Such a forecast depends on the historical data and assumptions about the future; it does not eliminate changes in scope, team, or delivery approach.
What P50 and P85 mean
In a forecast distribution, P50 and P85 denote the corresponding quantiles of the outcome. For a completion date, the meaning should be explained through the model used: what share of simulated outcomes fits within it. Without calibration, you cannot promise that actual projects will land within those boundaries with the same frequency.
For a manager, it is more useful to see the chosen level of caution, the input data, and the impact of scope changes than a single “likely number” without a basis. This article does not include schedule modeling, so no specific project dates or probabilities are provided.
How to estimate a project as a whole
A project is not just the sum of screens. There is overall architecture, integrations, shared components, migration, end-to-end scenario verification, and the move to production. Dependencies between parts can determine the calendar outcome more strongly than the complexity of an individual feature.
Start with a map of deliverables and boundaries. Then identify shared foundations and parts that can be delivered independently. Separately note decisions that many other tasks depend on. It is useful to validate them before estimating the detailed remainder of the work.
Separate fixed and recurring work
Creating a shared loading mechanism is one task; applying it in a specific form is another. The same applies to the design system, authorization, error handling, and test infrastructure. Reuse requires alignment with requirements and context validation.
For a project with multiple teams, add responsibility interfaces: who changes the contract, who provides test data, and who accepts the shared outcome. Unclear ownership can create delay even in technically simple areas.
In estimation, it helps to keep a separate list of coordination tasks and dependencies. This makes the forecast explainable without artificially inflating the technical score for every screen.
Consider integration quality
Components can work independently and still not form a ready-to-use end-to-end flow. Verification of permissions, data formats, retries, and errors is necessary at the boundaries. It should be included in the delivery plan.
Acceptance also needs a concrete basis: who verifies, what data is used, and what behavior counts as sufficient. If these conditions are clarified at the end, the issue may look like an “underestimated development effort,” even though part of the cause lies in an undefined readiness process.
Do not carry a simple sum over into architectural risk
If an unknown collaboration method or unusual data volume must be handled, it makes sense to validate the solution separately. Adding conditional percentages to every screen does not show whether the architecture can handle the requirements.
The result of research may narrow the options, confirm the approach, or show the need to change the requirements. Any of these outcomes is useful for estimation if the research question was chosen in advance.
Uncertainty, risks, and research before estimation
Unknowns should be named specifically. “Lots of risks” does not help with the next action. “It is unknown whether the service returns a stable task ID after a repeated request” already makes it possible to assign a check and an owner.
Separate requirements, technical solution, external dependencies, and organizational conditions. Each type of uncertainty calls for a different way to clarify it. A question for the product owner is not always solved by a technical prototype, and library compatibility is not clarified by additional discussion of the mockup.
What should the result of a spike be
An exploratory task, often called a spike, should answer a limited question. For example: does the library support the required keyboard-based table editing on target devices? The output is observations, constraints, and a recommendation for the next step.
Do not promise that uncertainty will disappear completely after the research. You can define a completion criterion: the normal and problematic scenarios have been checked, the constraints recorded, and the option for further implementation selected. This makes the work manageable.
It is also important not to pass off a prototype as a production component. A proof of concept may not include accessibility, robust error handling, support, or operations. If the code will be reused, assess the effort required to bring it up to the needed quality separately.
Contingency should have an explanation
It is more useful to tie contingency to risks and the level of commitment. In one project, the main risk is changing requirements; in another, it is integration with an external owner. The same markup for all tasks shows neither the cause nor the possible action.
Do not add several contingencies for one cause: a high uncertainty score, added hours, a separate risk percentage, and an extra buffer on top of that. This setup may look cautious, but it can count the same event multiple times.
The conditions for review should be agreed in advance: requirement changes, prototype confirmation, a new contract version, or a team change. Re-estimating when new data arrives is a normal part of the process.
Task Estimation Template for the Team
Below is a copyable template. It is not a mandatory standard form. Use only the fields that help your decision; for a small change, a short note is enough.
| Field | What to record |
|---|---|
| User outcome | What will become possible after delivery |
| Scope boundaries | What is included in the current task and which adjacent outcomes are split out separately |
| Basis | Requirements, mockup, contract, link to discussion |
| Acceptance criteria | Verifiable readiness conditions |
| Data and roles | Sources, constraints, permissions |
| States | Success, empty result, error, waiting, retry, and cancellation, if applicable |
| Components | What will be reused and what needs to be created |
| Quality | Accessibility, devices, performance, and other agreed requirements |
| Unknowns | Specific questions instead of assumptions |
| Dependencies | Owner, expected result, and impact on schedule |
| Analogues | Completed tasks and material differences |
| Chosen method | What exactly is being measured or assessed and in what units |
| Estimate | Value or range with conditions |
| Verification | Review, testing, integration, and release as part of the outcome |
| Revisit | The event after which the estimate is updated |
For a project, add shared components, architecture checks, end-to-end acceptance, and a delivery plan. Do not copy the same infrastructure effort into every ticket. Link shared work to dependent tasks.
Example of a short entry
Training wording: “After uploading the agreed file, the user sees the validation result and can proceed to field mapping. Empty state, format error, and reselect are included. A ready validation contract is assumed; recovery after reload is split out separately. Before estimating, the file size limit must be confirmed.”
There is still no number here, but there is already something to estimate. After the question is answered, the team can compare the task with analogues or run Planning Poker. This sequence reduces differences in interpretation.
Step-by-step estimation process for the team
The workflow can be built as a sequence of decisions. It is not necessary to hold a separate meeting for every step: what matters is preserving the actual results.
- Define the decision that requires the estimate. Choosing an option, planning an iteration, forecasting a release, and making a proposal to a client all require different levels of detail.
- Record the outcome and boundaries. Align on the definition of done and the scope of required verification.
- Break down functions, data, and states. Prepare material for COSMIC and SNAP if needed.
- Assess implementation specifics. For existing code, use metrics as signals; for new work, use a matrix and prototypes.
- Identify unknowns and dependencies. Assign specific questions and checks.
- Compare with the team’s history. Use analogues or relative estimation on an agreed scale.
- Build the forecast. Account for resources, sequence, expectations, and the chosen level of caution.
- Return to the estimate after execution. Review the reasons for variance and improve the basis for the next decision.
The output should not be a large document for the sake of documentation. A record is enough for another participant to understand what is promised, what it is based on, and what may change. That makes the estimate verifiable.
How to use AI when estimating tasks
AI can be used during preparation: extract scenarios from a description, suggest questions, map requirements to wireframes, or build a draft state table. This helps structure the discussion if a person reviews the result.
Do not treat a number produced by a model as a COSMIC or SNAP measurement. A formal calculation requires rules, a boundary, and traceable justification. A number without a list of counted elements does not become objective just because the explanation sounds confident.
For code metrics, a reproducible analyzer with a fixed configuration is preferable. AI can help explain a problematic handler and suggest a refactoring option. But the final score and preservation of behavior are verified by the appropriate tools and tests.
A useful task for preparing an estimate
You can phrase the request like this: “Identify the user outcome, states, external dependencies, and unknowns. Do not assign hours without analogs. For each assumption, specify what needs to be confirmed.” Such a draft is easier to review than an unsupported estimate.
If internal documents are used, follow the accepted rules for access and data handling. The convenience of the tool does not change who owns the information. Requirements review remains the team’s responsibility.
Common estimation mistakes
| Mistake | Why it gets in the way | How to fix it |
|---|---|---|
| One score instead of all characteristics | Size, risk, and timeline get mixed together | Keep the profile and the forecast separate |
| Number of screens as the whole estimate | States and integrations get lost | Map wireframes to scenarios |
| Converting points to hours | Hides differences in tasks and context | Use the team’s history and an explicit forecasting model |
| CFP plus SNAP points plus code complexity | Different units get added together | Tie metrics to requirements without inventing a custom common standard |
| Low function complexity as proof the task is easy | Distributed logic stays out of view | Analyze the scenario and dependencies |
| Unknown marked as zero | Lack of data looks like simplicity | Separate question status and verification |
| Maximum score for any unknown | The reasons and the chance to clarify are lost | Name the subject and the impact of the unknown |
| Multiple buffers for one reason | Double counting occurs | Trace each buffer back to its basis |
| Only the success scenario | Errors and recovery appear too late | Describe states in advance |
| Dividing the total by the number of people | Dependencies and availability are ignored | Build the sequence and the resource plan |
| No comparison with actuals | Errors get repeated | Analyze the causes, not just the variance in the number |
Why more detail does not always improve accuracy
Breaking a large unknown task into dozens of unknown parts can produce a nice-looking table, but not new knowledge. If every line depends on an unconfirmed technology, you need to verify its applicability first.
Detail is useful when it reveals composition and boundaries. Extra decimal places do not increase reliability. Show precision that matches the evidence available.
How to check the quality of the estimate itself
After the work is done, it is useful to compare not only forecast and actuals. Find out what changed: scope, definition of done, people availability, an external contract, or understanding of the existing code. Each cause requires its own improvement.
If the estimate was correct under the stated conditions and the conditions changed, that should be reflected in the history. If work existed in the requirements but was missed in the breakdown, improve the analysis. If the team systematically forgets release and acceptance, clarify the definition of done.
What data to save
Save the original scope, assumptions, chosen method, forecast, significant changes, and actual result. It is helpful to know when new information appeared. This makes it possible to avoid rewriting the estimate history after the fact.
The observations themselves do not have to become individual developer monitoring. For team learning, the reasons at the task and process level matter. Comparing people across non-comparable tasks provides little useful input for the next forecast.
When to review the criteria system
If a criterion always gets the same value and does not affect decisions, it may be possible to remove it. If recurring deviations are tied to a missing factor, add a specific observable field.
Do not change the scale just to make it look nicely aligned with past results. A new rule should help future decisions. Test it on new completed work and keep the matrix version.
Frequently asked questions
Which complexity estimation method is the most accurate?
The methods measure different things. COSMIC measures functional size, SNAP measures nonfunctional size within its rules, metrics analyze code, and statecharts describe behavior. Forecast accuracy for the work depends on the requirements, data, and the model used to convert size into effort and timeline.
Can you estimate a project based on wireframes alone?
Wireframes help build an inventory. For a defensible estimate, you need scenarios, states, data, integrations, and definition-of-done criteria. A static happy-path screen usually does not answer all of those questions.
Is COSMIC just the number of user actions?
No. The method uses functional processes and data movements within a defined boundary according to its own rules. A click list may be input for analysis, but it is not the same as the formal CFP size.
Does SNAP account for any UI complexity?
Not automatically. The requirement has to match the method’s scope and rules. An arbitrary coefficient for visually rich design is not a SNAP measurement.
Can COSMIC and SNAP be combined into one estimate?
The results can be used as different inputs to your own effort model. A simple sum of units does not create a standard measure. You need to show how the model is built and where it applies.
How is Cognitive Complexity different from Cyclomatic Complexity?
The first focuses on the structural difficulty of understanding control flow; the second focuses on linearly independent paths. They provide additional signals, but they do not measure the entire architecture or define development hours.
How many tests are needed for a given cyclomatic complexity?
You cannot derive a complete test set from a single metric. Coverage criteria, data, path reachability, asynchronicity, and product requirements all matter. Independent paths are only part of the picture.
Do you need to implement XState for estimation?
No. You can start by describing states and transitions in a table. Choosing a library is a separate engineering decision. The model is useful even before implementation.
Can you use your own complexity matrix?
Yes, if it is clearly labeled as an internal tool, the criteria are defined, and the unknowns are not hidden. It cannot be presented as a validated standard or a universal translation table into hours.
How many hours is one Story Point?
There is no fixed universal conversion rate. Forecasting uses the team’s history and the chosen assumptions. A change in context may require revisiting the model.
Is Planning Poker mandatory in Scrum?
No. It is one way to discuss relative estimates. The team can choose another approach that fits the work and the data available.
Do Nielsen heuristics help estimate effort?
They help identify the problem and clarify the requirements. Effort is estimated after the solution is chosen. The importance of the problem to the user is not the same as the cost of fixing it.
How do you estimate a task when there is a lot of uncertainty?
List the questions that affect the decision and choose a way to test them. Give a rough estimate only with explicit assumptions. If the implementation approach itself is unknown, research may be more useful than a large number.
Should tasks be re-estimated after work has started?
Yes, when significant new information appears or requirements change. Keep the original estimate and the reason for the change. This makes it possible to learn and adjust the forecast without rewriting history.
Sources and scope of use
Definitions of the methods are based on the primary sources COSMIC, IFPUG, SonarSource, Stately, Scrum Guide, Scrum Alliance, Mountain Goat Software, React, W3C, and Nielsen Norman Group. Links are provided next to the relevant statements. The methods are compared by object, available inputs, output, and limitations.
The training import, factor matrix, card template, and arithmetic examples are offered for explanation. They do not confirm specific performance and do not replace official formal measurement guidelines. The team should verify their suitability for its own work.
How to prepare a project estimate with Vladimir Lomtev's studio
For AI projects, the studio's focus areas apply to process analysis, data preparation, MVP development, and integration testing. In the preparation stage, you can break down one user scenario, describe the data and external dependencies, and then define acceptance criteria for the pilot solution. These are concrete grounds for a future estimate, without promising fixed accuracy or savings.
The first step is to choose a process and gather its current description: who uses the system, what data is available, what constraints are mandatory, and what result needs to be accepted. If AI integration is required, it is useful to separately define the role of the model and the actions that remain under human control. Discuss the task.
Where to start when estimating task and project complexity
Start with the outcome and boundaries, then break down the data, states, and constraints. Use COSMIC and SNAP where a formal size is needed, code metrics for an existing implementation, statecharts for behavior, a matrix for a relative profile, Story Points for team discussion, and Nielsen heuristics for usability checks.
After that, build your effort and schedule forecast on suitable data and explicit assumptions. Keep track of unknowns, dependencies, and review conditions. A useful estimate explains the decision, can be checked after completion, and improves future planning.